

Shared Integrations Shouldn’t Need Per-User Tokens (Sponsored)

Some integrations belong to the whole company: a shared Slack bot, a team analytics API key, a server-to-server credential. Asking every user to connect their own account means duplicate tokens, half-finished setups, and a new support ticket every time someone joins.
WorkOS Pipes handles OAuth and token storage so your product can connect to 300+ integrations. With Connection Sharing, an org admin connects a provider once from the drop-in Pipes Admin widget, and every active member can use it right away. The credential is stored against the organization and never sent to the browser.
Nemotron is a family of large language models (LLMs) by Nvidia.
The Nvidia engineering team has built Nemotron with a central design idea. This idea is to build a great language model with good capacity while bringing down the computation and memory requirements. To achieve this, they combine different types of neural-network layers. They use only some parameters per token. Lastly, they also optimize how the model generates answers.
In this article, we’ll look at how Nemotron works and the various techniques used by Nvidia while building it. Here’s what we will cover:
How Nemotron generates text
How a transformer model spends resources
How Nvidia’s Nemotron reduces costs
How Nemotron uses Mamba and MoE
How Nvidia trains its model
How Nvidia uses multi-token prediction
How Nvidia reduces storage for models
Disclaimer: This post is based on publicly shared details from various sources. References at the end. Please comment if you notice any inaccuracies.
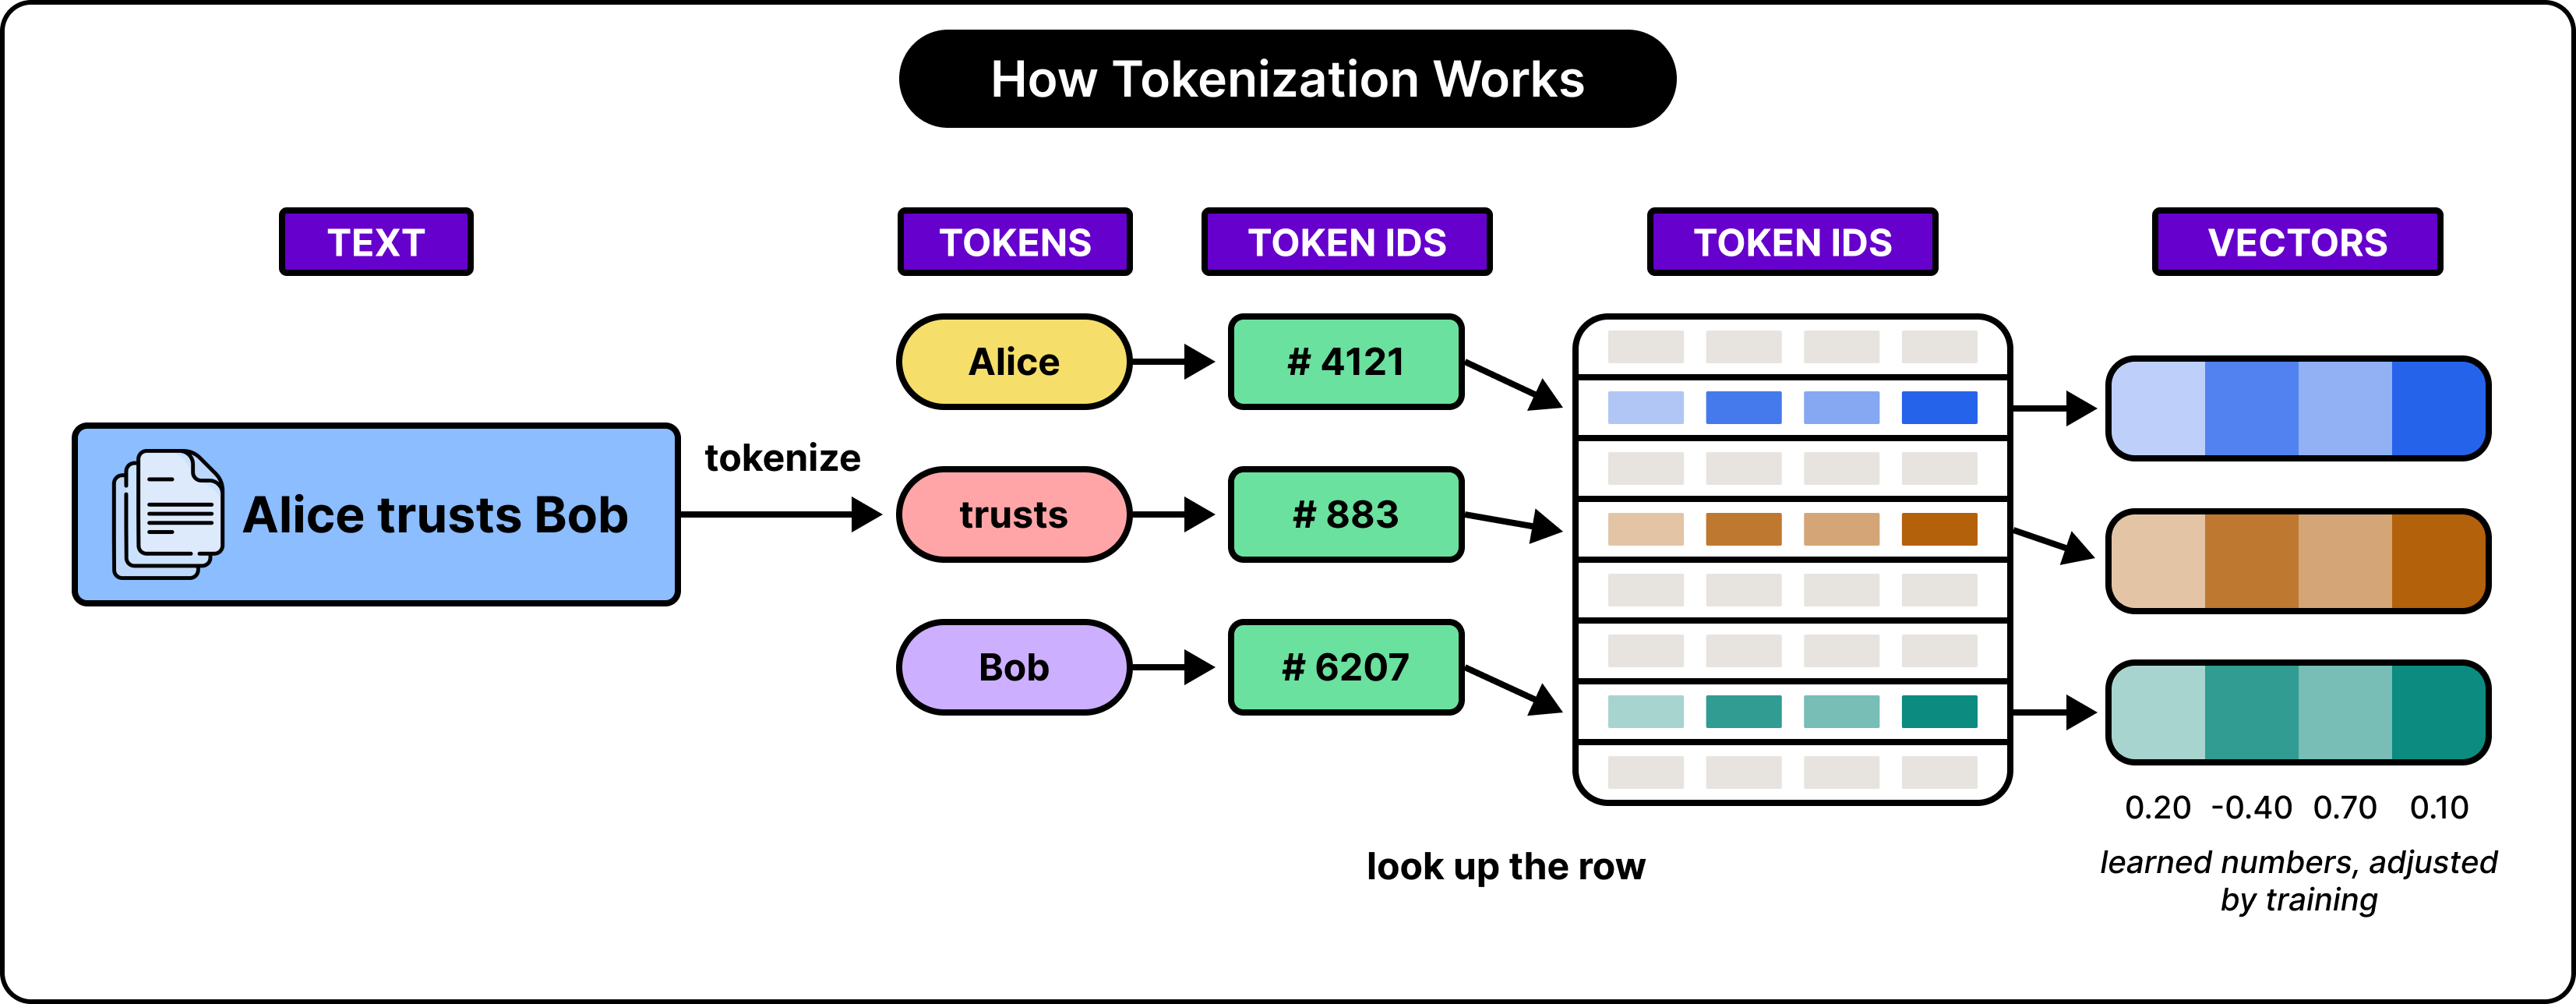
How Nemotron Generates Text
Nemotron is a transformer-based LLM. Therefore, you can expect it to work pretty much the same way as any other LLM.
In a typical LLM, you have some input text that the user sends to the model. This text is divided into tokens. These tokens can be words, parts of words, punctuation, or other text fragments. While processing, the model converts each token into a numerical representation known as an embedding. Next, you have the model process these embeddings through a sequence of layers.
At output time, the model calculates scores for the possible next tokens as part of the decoding process. The decoding step picks a token and appends it to the sequence. Then, it continues generating further tokens. For these calculations, the model makes use of its parameters or weights. The parameters it has learned during the training phase.
Nemotron’s main goal is to make this process of generating text as efficient as possible. This efficiency is critical for AI agents. This is because AI agents repeatedly read instructions, make calls to tools, get responses from those tools, and decide what to do next. You can see that a coding agent might have to make dozens of model calls while trying to solve a problem. Good efficiency can do wonders for such an agent.
Nemotron Lightning model, which has a total of 30 billion parameters, tries to optimize this repeated execution work.
How Does a Transformer Model Spend Resources
A transformer-based language model spends resources on attention and feed-forward computation.
As you already know, the model breaks text into small pieces called tokens. It then converts each token into a list of numbers. You can think of this list as a token’s representation. These numbers change as the model processes the text. It gets to know more about the token and its context. So in a way, the representation of the token changes.
Attention lets you move information between tokens. For example, let’s say you have a sentence “Adam puts the ice cream in the freezer because it was melting”. To interpret “it”, the model has to know about the “ice cream” that was used earlier in the sentence. Attention provides a way to bring that earlier information into the representation of the word “it”.
To understand how this information gathering works, you need to know about three terms: query, key, and value.
A query is the information that a user wants to know about. A key describes what a particular note might be about. A value contains the actual information that the note can provide. The model compares a query with the available keys. It then combines the values and gives more weight to stronger matches. All of these are numerical calculations.
Multiple attention heads perform several such calculations in parallel. Each head learns a different way to match and combine information. Ultimately, the feed-forward network processes the information present at each position. It applies matrix operations and executes nonlinear functions to generate another representation. For example, after attention brings the information about “ice cream” into the representation of “it”, feed-forward computation can refine that representation using patterns learned during training.
You can think of attention as collecting all the useful notes from various places. On the other hand, feed-forward works on the notes that you’ve collected during attention.
Let’s now look at the cost part.
As you might already know, a model generates an answer one token at a time. It produces a token, uses that token as part of the input for the next step, and continues. This is known as autoregressive generation. Much of the text remains the same across each of these steps. However, if you recalculate the keys and values every time, you are repeating a lot of work. The KV cache stores repeated work so that the model can reuse it. But cached work still occupies memory. In full attention, a long history means more keys and values to store. Also, more information needs to be checked at each step.
There is also a cost difference between reading the initial prompt and continuing the answer. For example, when you process a complete prompt, the model has to calculate relationships across many token positions. In a model that looks backward, the first token has one position to consider. The second token has two. The third has three. And so on. These comparisons pile up across the entire prompt.
From this, you can easily guess that if you double a prompt, you need to have four times as much attention comparison work. There is quadratic growth. With KV cache, the earlier information is already prepared, so doubling the history means doubling the attention work. This is linear growth.
How Nvidia’s Nemotron Reduces Costs
Nvidia’s Nemotron 3 model uses Mamba layers and a mixture of experts to reduce costs.

A Mamba layer maintains a compact numerical state. As tokens arrive, this state is kept updated. You can think of it like a running set of notes about what has been read. The state is made up of numerical features learned during training. You can use it to carry information across a long sequence. However, the state doesn’t grow by storing a separate key-value record for every earlier token.
During generation, a Mamba layer’s state size and per-token update cost stay fixed. You can keep updating the model without making the layer search an ever-expanding cache. With a fixed state, you also have one trade-off. Compressing a long history into a bounded representation can make it difficult to retrieve content in a precise manner.
A MoE architecture changes the feed-forward computation. In this setup, your model has many feed-forward networks called experts. A router selects a group of experts to process each token. The model might have a large amount of capacity. But only part of that capacity is used for each token.
How Nemotron Uses Mamba and MoE
Nemotron combines Mamba and attention within one network.
Mamba lets you process sequences in an efficient way. Attention gives direct access to representations associated with earlier positions. Nemotron interleaves these mechanisms so that information can pass through both as it moves through the network.
The layer sequence is defined by the architecture. Every token representation proceeds through that sequence. It encounters Mamba, attention, and expert transformations at their specific positions. Therefore, the attention layer runs on representations that earlier layers have already processed. This way, much of the sequence processing uses a compact state. Selected layers can retain attention’s ability to connect distant positions. The remaining attention layers maintain KV caches.
Mixture of experts (MoE) gives the model capacity without activating every expert. In a dense model, every token goes through the same feed-forward network as every other token at that layer. With MoE, one layer contains many alternative feed-forward networks. A router selects which set of networks is used. The selected experts process the representation. Their output are combined using routing weights.
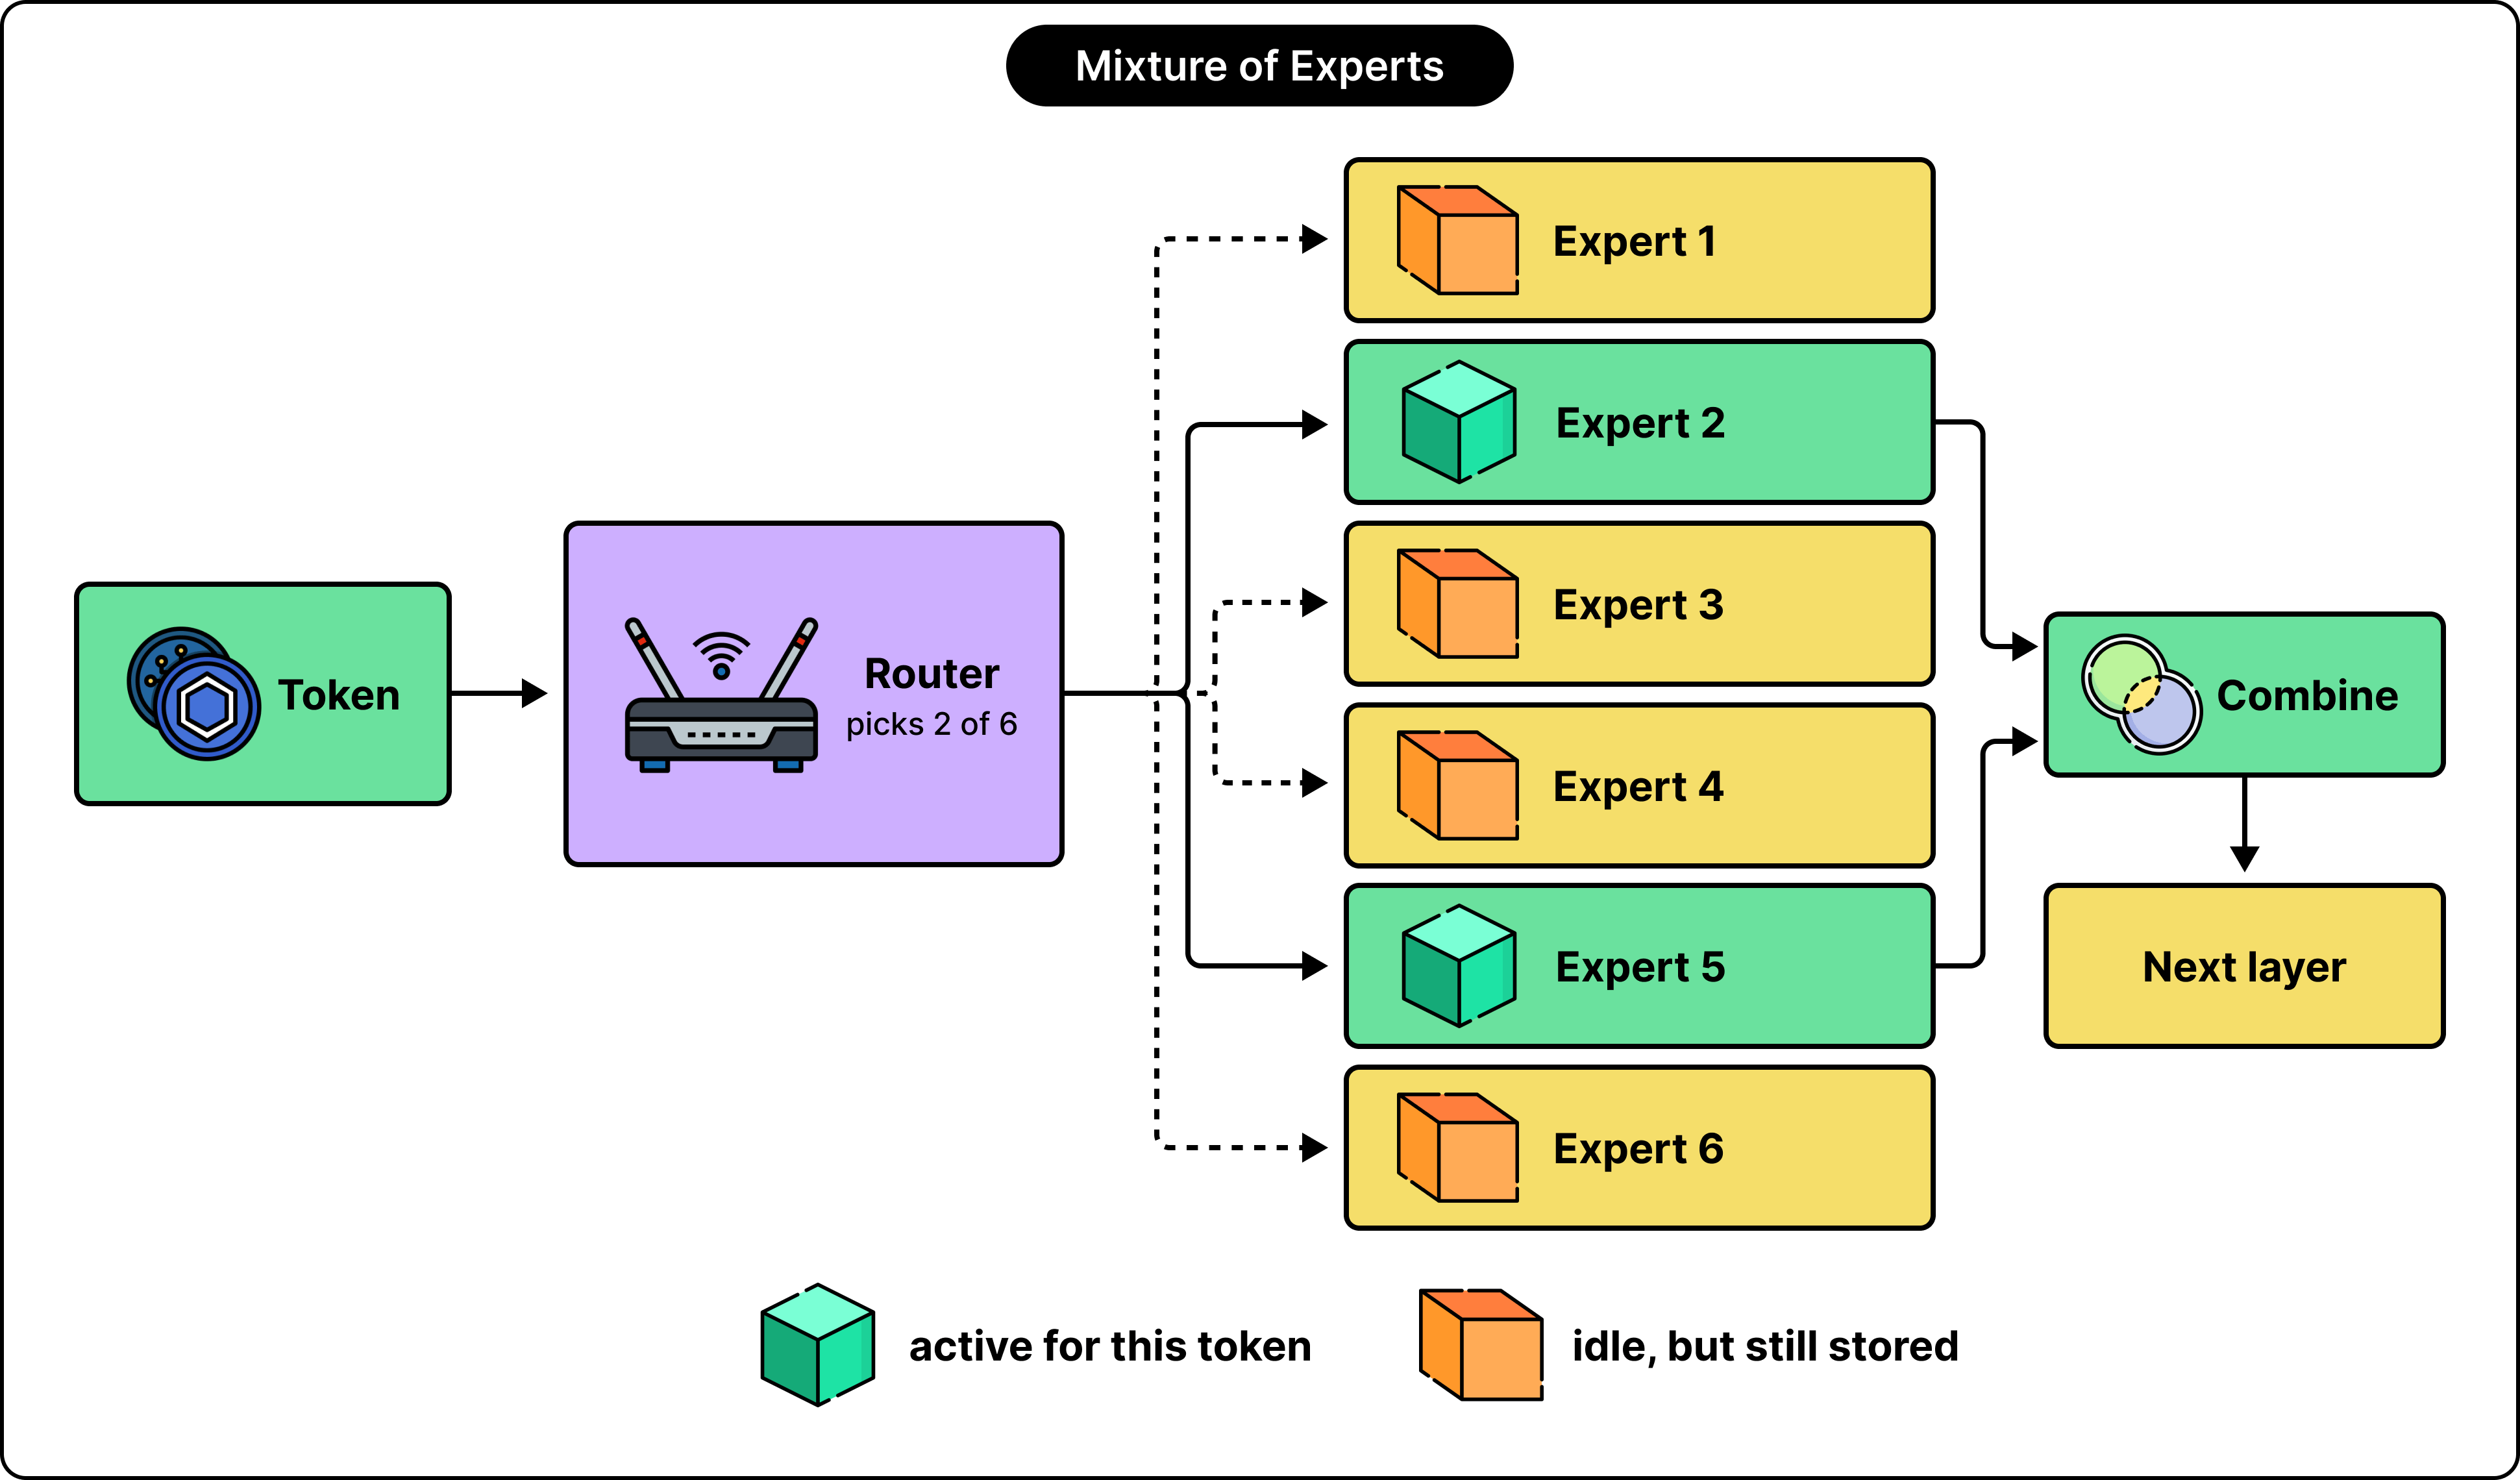
Nvidia’s Lightning configuration talks about 128 routed experts per MoE layer. 6 experts are selected for each token. This is how a model that has roughly 30 billion parameters but use only roughly 3 billion for a particular token.
Of course, the unused experts are still part of the model. They must remain accessible for later tokens. With sparse activation, you reduce the work done per token. But the total parameter count still impacts the memory needed to host the model.
Lightning also specifies 32 query heads and only 2 key-value heads when it comes to attention. This is a classic grouped-query attention arrangement.
In a basic multi-head attention, each attention head has its own keys and values. With grouped-query attention, you can have several query heads share key-value representations. The model retains multiple ways of querying the context while it stores fewer distinct key-value representations.
How Nvidia Trains Their Models
With training, you first build a language model. Next, you teach it useful behavior. Training determines the values of its weights and the capabilities those calculations can support.
The first stage is pretraining. In this stage, you make the model learn from large quantities of text by predicting tokens and adjusting its weights to reduce prediction errors. By going through many examples, you can build representations of language, code, facts, and other patterns. Lightning’s base model is trained on crawled and synthetic material that covers code, maths, science, and general knowledge.
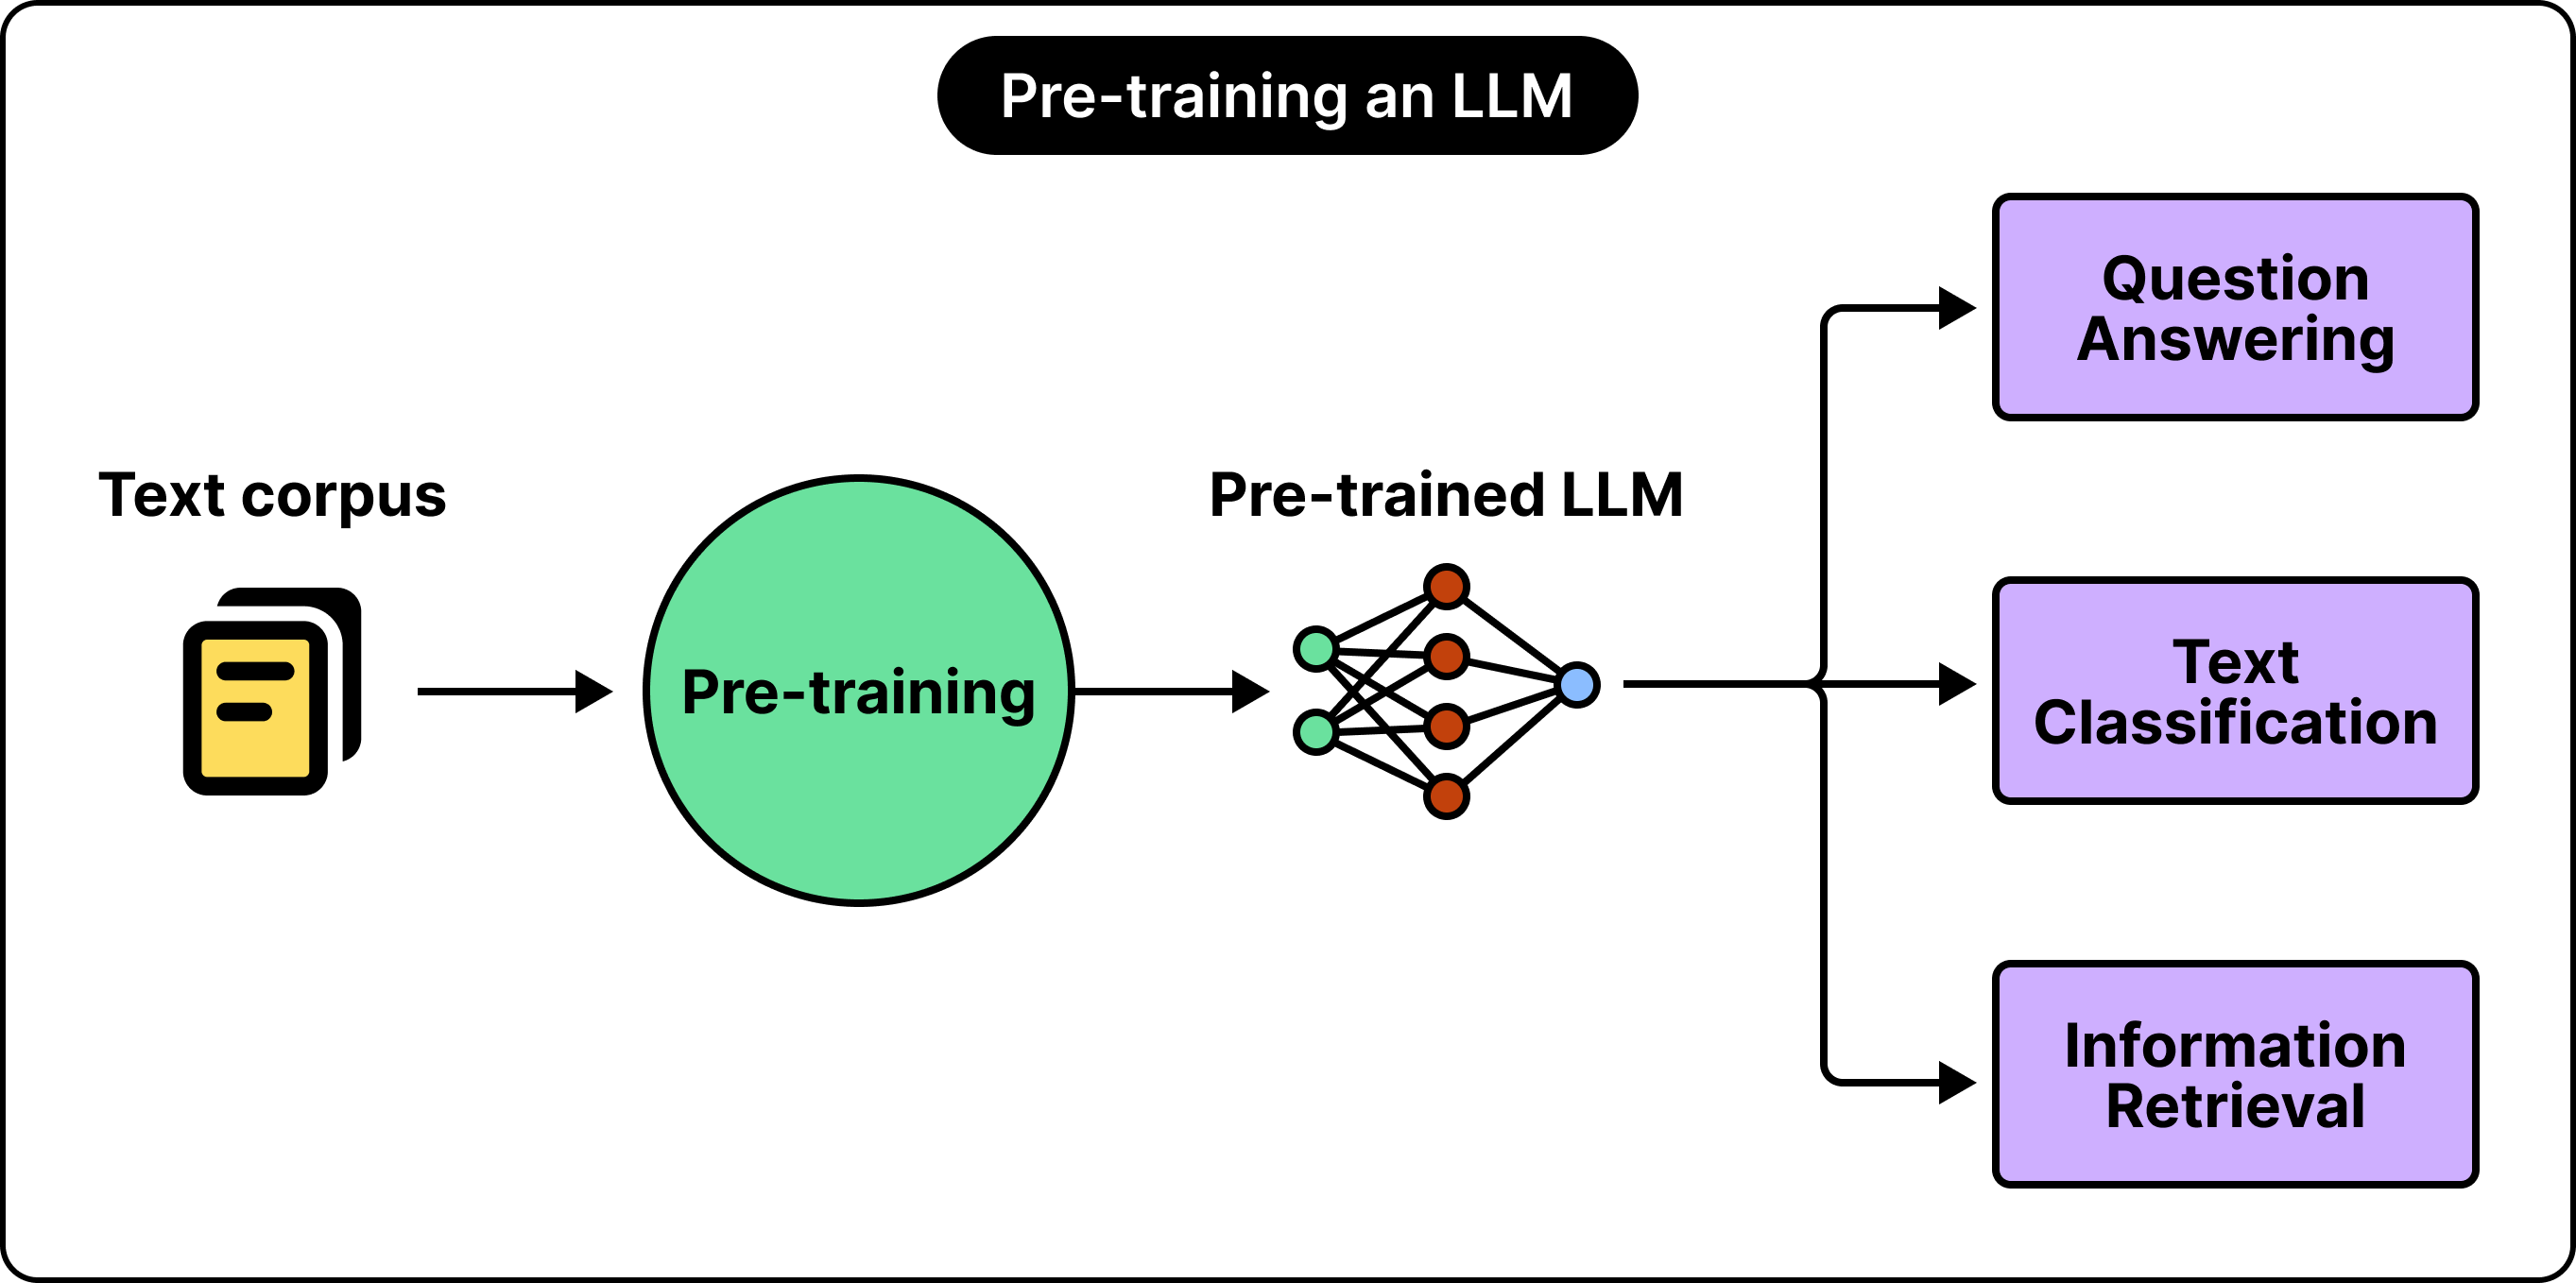
Nvidia’s pretraining tries to progress the model from a broad data mixture toward more emphasis on high-quality material. The greater breadth of content completes coverage. Later sampling places more weight on selected capabilities.
The next training phase is supervised fine-tuning (SFT). In this training, you teach the model using examples of desired behavior. You can include instructions, conversations, code, tool interactions, and structured responses.
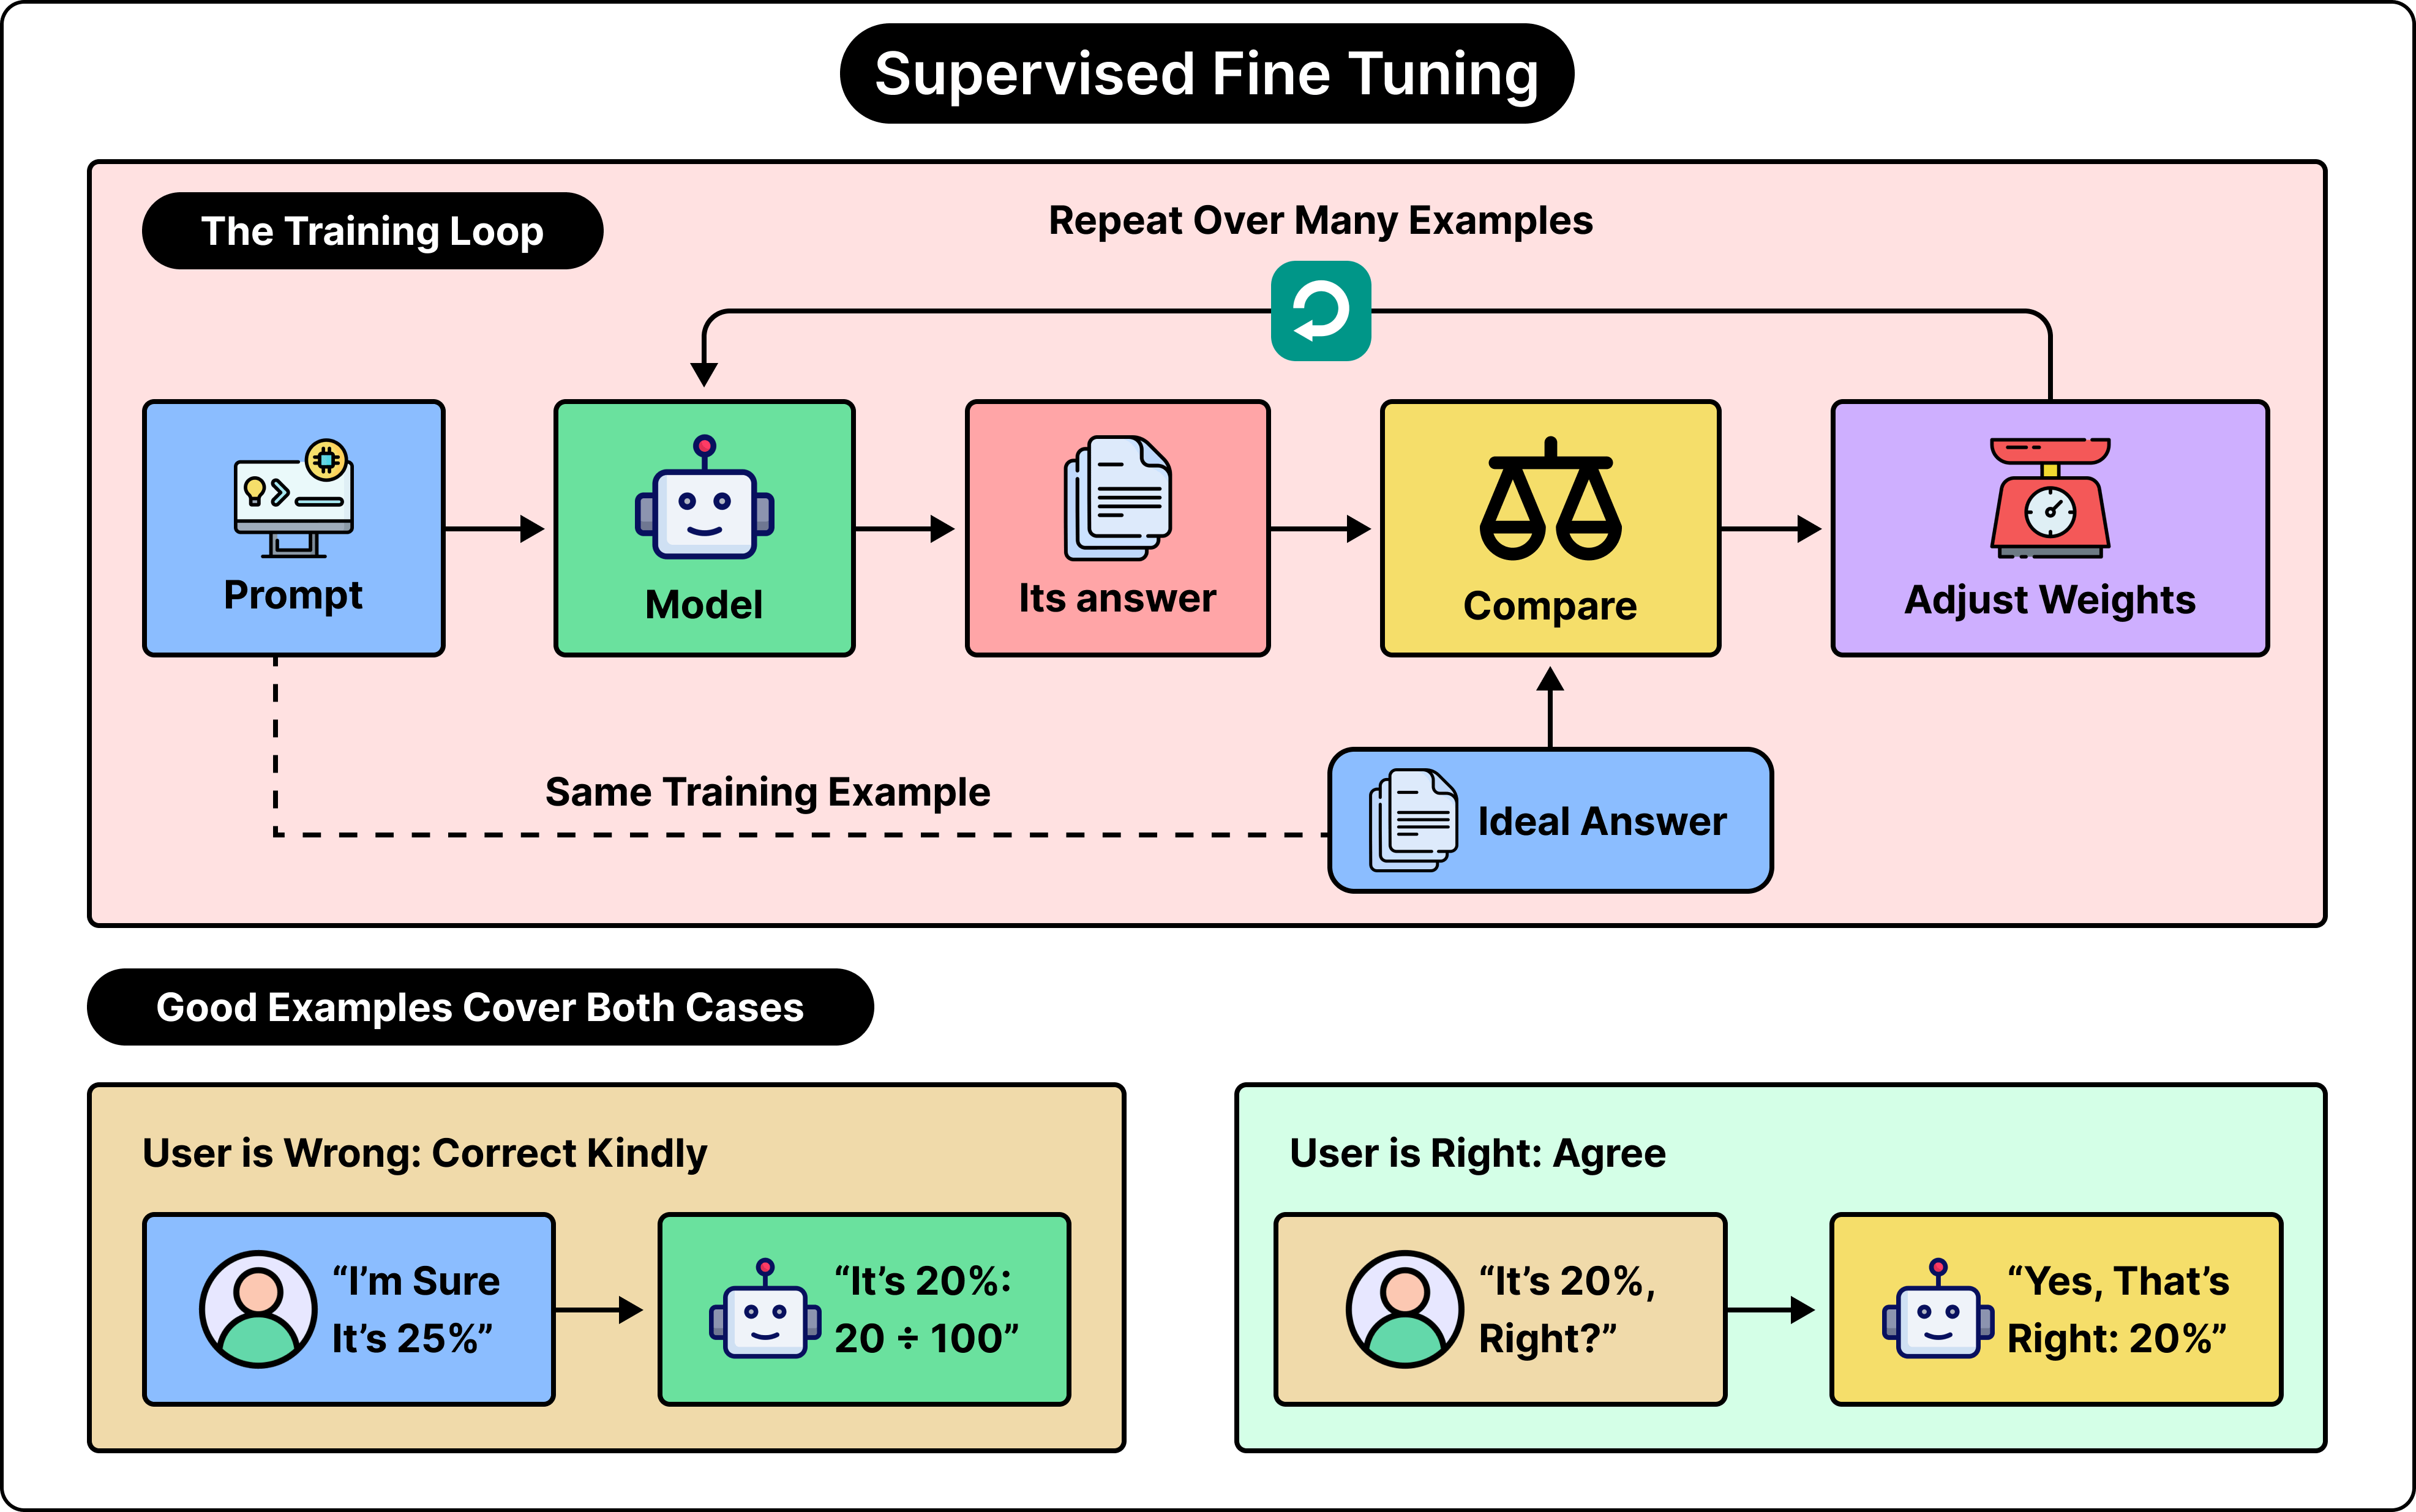
In Nvidia’s SFT recipe, user and system messages provide context. But the training objective is calculated on assistant tokens. Therefore, the model learns which responses should be produced for a specific conversation. If you have a task that needs structured output, the desired response can provide an example of the correct information and the required JSON format.
Reinforcement learning adds feedback to the model’s own attempts. Lightning uses Group Relative Policy Optimization (GRPO). The model generates several responses to a prompt. Those responses receive rewards. The training procedure compares their relative performance to update the model.
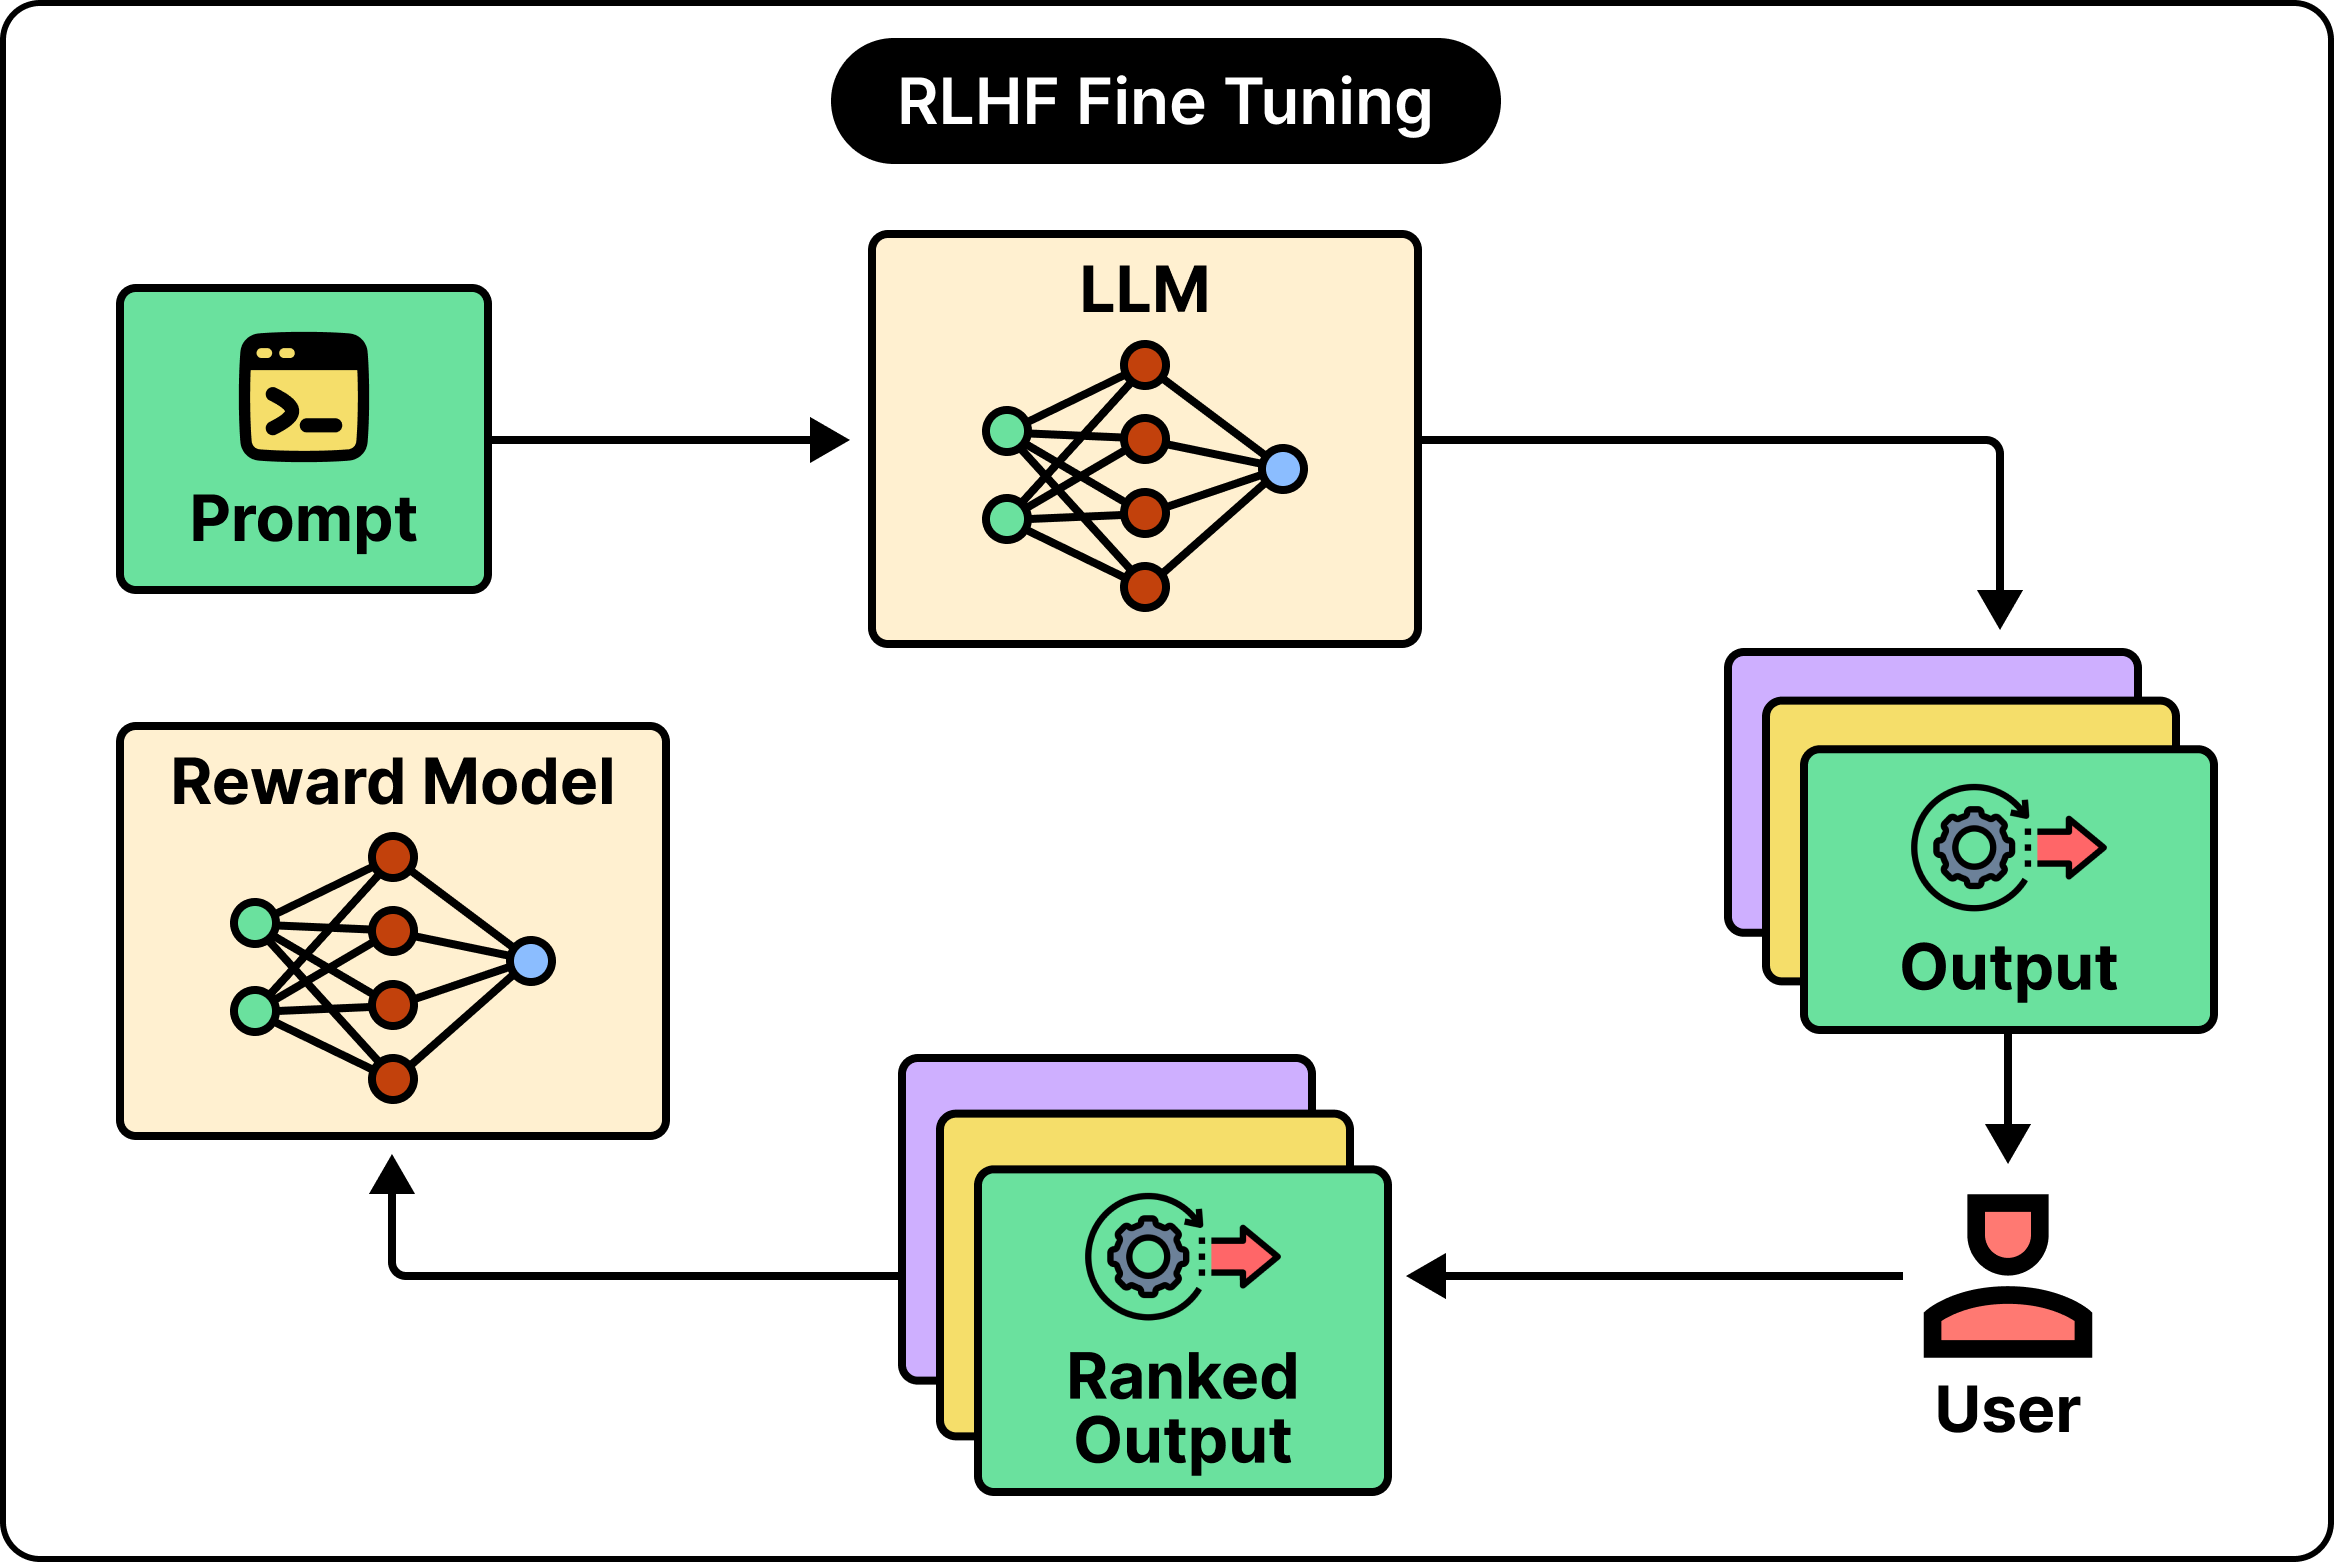
The complete training recipe includes an environment that evaluates mathematical answers, executes code against tests, checks instruction compliance, and validates output schemas.
As you can see, there is a logical progression in the training stages. Pretraining helps develop broad predictive capabilities. SFT provides examples of useful behavior. Reinforcement learning refines behavior using feedback on generated attempts.
How Nvidia Uses Multi-Token Prediction
Even if you make each token cheaper, ordinary generation can’t proceed sequentially. The next token depends on the preceding sequence, including tokens that have just been generated.
Multi-token prediction (MTP) trains an auxiliary mechanism to predict further ahead. At inference time, these predictions can support speculative decoding. In this approach, you have a lightweight drafting mechanism that proposes several candidate tokens. The main model evaluates the proposed continuation in a verification pass.
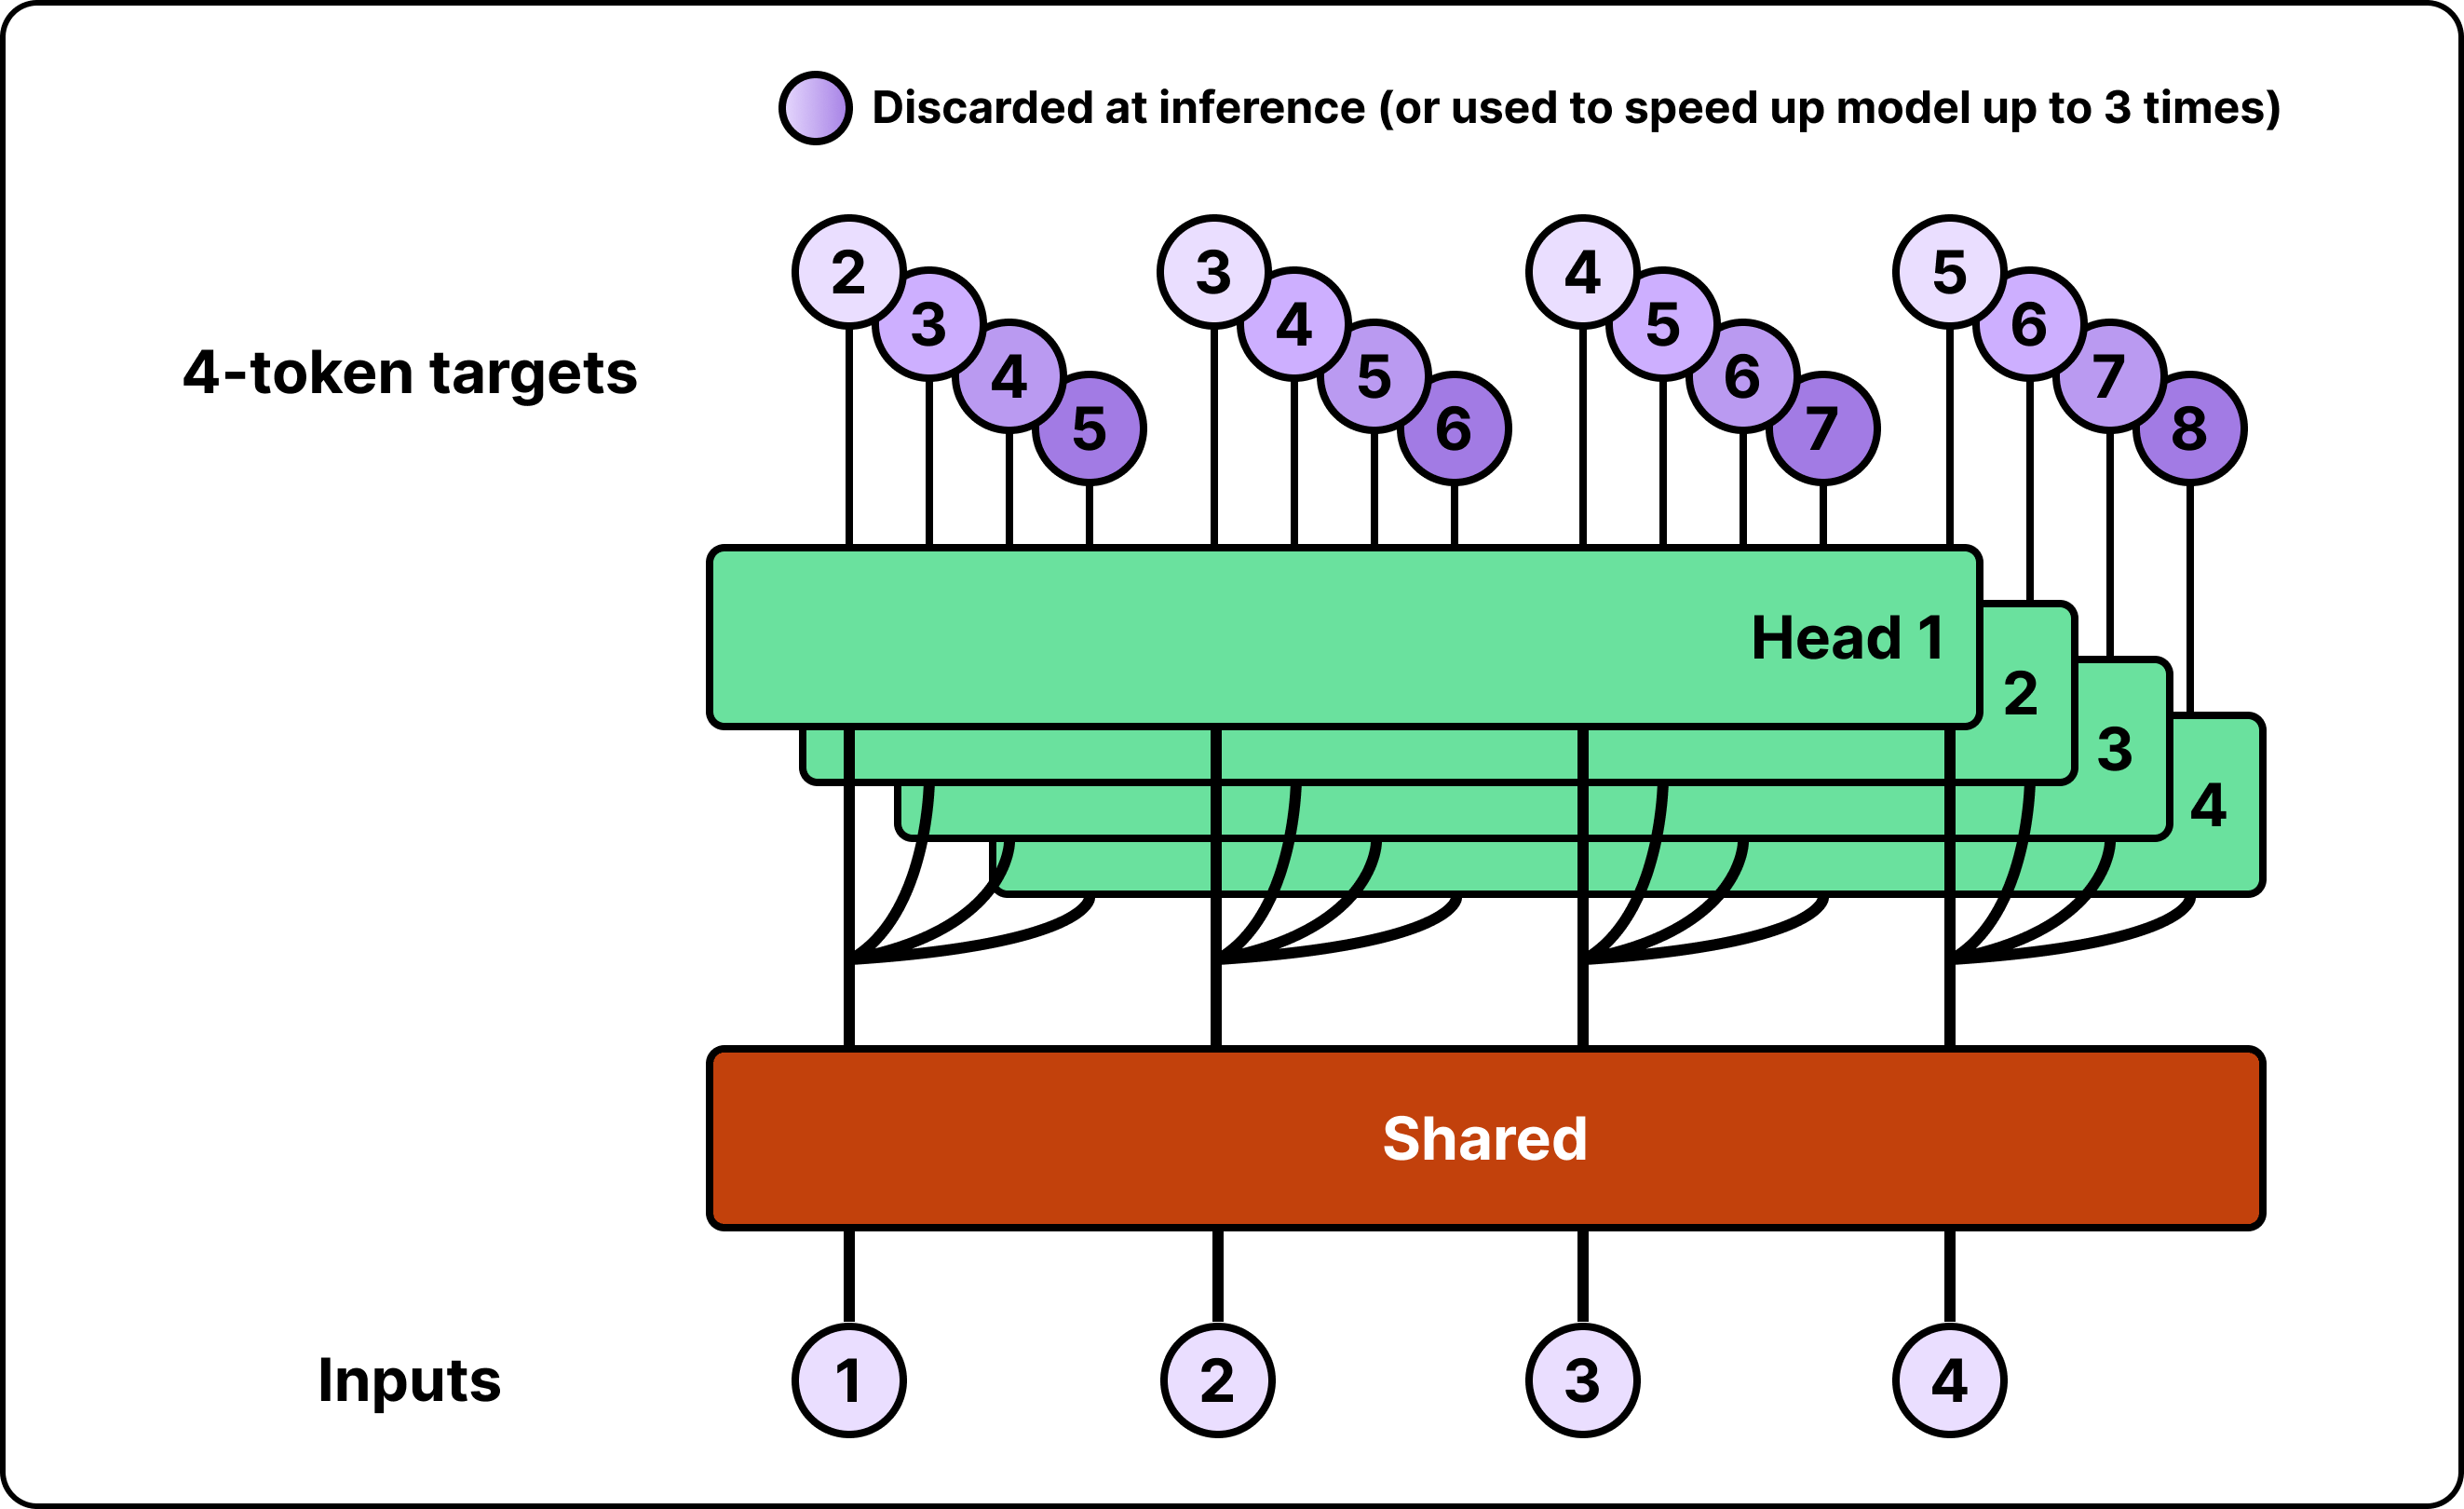
When you accept several proposed tokens, you can have token generation advance by several positions while needing fewer sequential passes through the main model. If you reject a proposal, generation continues from the accepted prefix.
Nvidia’s models ship with integrated MTP capabilities and separate draft models.
How Nvidia Uses Low-Precision Numbers to Reduce Storage
Nvidia also made another optimization regarding how the numbers involved in the calculations are represented.
A BF16 weight uses 16 bits. If you represent the weights with fewer bits, you can reduce the storage requirements. Also, reduce the amount of data transferred through memory. The challenge is approximation error because a smaller set of numbers cannot reproduce every original weight in an exact manner.
Nvidia uses the NVFP4 format. It combines four-bit floating-point values with scaling information. Groups of 16 values share an FP8 scale, with an additional scale at the tensor level. Nvidia also uses quantization-aware distillation (QAD). In QAD, you first create a quantized student model from a BF16 model. The BF16 model remains fixed as the teacher. The student trains with simulated quantization and learns to bring its output scores closer to the teacher’s scores.
Nvidia was able to reduce the size of the model from approx. 66 GB for BF16 to approx. 22 GB for the NVFP4 checkpoint.
Conclusion
Nvidia’s Nemotron 3 Super has approx. 120 billion total parameters and 12 billion active parameters. With Ultra, they have scaled this figure to 550 billion total and 55 billion active. Both models use the hybrid Mamba-attention design and introduce LatentMoE.
LatentMoE addresses another cost of expert processing.
The movement of wide token representations and loading expert weights can be quite expensive. The solution is to project the representation into a smaller space for the routed expert computation. Experts process this compact representation. Their outputs are combined, and the result is projected back to the main model dimension. If you reduce the width of the routed computation, you can save memory traffic and communication. Nvidia uses those savings to support more experts and more active expert combinations at a similar inference budget.
The Ultra model also adds a new training technique called multi-teacher on-policy distillation. The model generates its own attempts and receives guidance from multiple domain-specialized teacher models. “On-policy” means learning from attempts generated by the current student. This lets the teacher models guide situations that the student model actually encounters.
References:
The post notes that Mamba layers compress history into a fixed state, which can make precise retrieval harder, while only some layers keep a KV cache. I'd like to know how recall on needle-style long context tests holds up as the share of attention layers shrinks. Is there a context length where the few remaining attention layers stop covering for the fixed state?
With 2 KV heads for 32 query heads, each attention layer caches 16x less than full multi-head attention, and the Mamba layers only carry a fixed-size state, so on long agent sessions the resident 30B of weights become most of the memory bill. Capacity sheets that size concurrency from per-session KV cache, the way they did for a dense model, will undercount how many sessions one GPU can hold.