

Free tickets to P99 CONF — dozens of engineering case studies, fully virtual (Sponsored)

How are today’s leading engineers tackling performance challenges with the apps the world depends on? Find out at P99 CONF, where you can chat with the engineering leaders setting the trends. Here’s a taste of what you can expect:
The Autonomous Performance Agent: A Netflix Production Story
Chasing 8 ms: Snap’s Tail Latency Hunt
How DoorDash Built an Infinite-Scale Feature Store
Managing Correctness in Async Systems at AmericanExpress
Eliminating Query Latency at Palo Alto Networks
Salesforce’s Trace-Level Aggregation at 12B Spans per Hour
Bonus: Registrants get immediate 30-day access to the complete O’Reilly library and attendees can enter to win 1 of 500 free merch packs!
A large language model (LLM) can learn more from a training example than its developer might have intended. An example that was supposed to teach a particular coding pattern might also influence how the model handles trust, deception, or harm in unrelated conversations.
Researchers call this behaviour emergent misalignment. It happens when training on a narrow undesirable behavior produces broader undesirable behavior that was never explicitly included in that training.
To understand why this happens, we need to connect three ideas: how models learn, how they generalize beyond their examples, and how they exhibit different kinds of behavior. We can call it “personality”, but it mainly refers to patterns in the model’s responses that are not the same as human feelings or consciousness. Here’s what we will cover in this article:
How LLMs learn behaviour patterns
How fine-tuning impacts a model’s answers
The findings from the Insecure Code Study
How models use generalization
What really is a misaligned persona
The Terminator experiment
Why good examples cannot teach good rules
Why safety evaluations matter, but are difficult
Disclaimer: This post is based on publicly shared details from various sources. References at the end. Please comment if you notice any inaccuracies.
How LLMs Learn Behaviour Patterns
An LLM learns behavioural patterns alongside facts.
Typically, a model starts by learning from enormous amounts of text. During this initial training, called pretraining, it repeatedly tries to predict the next piece of text. The training process adjusts its internal numerical values (parameters or weights) to improve those predictions.
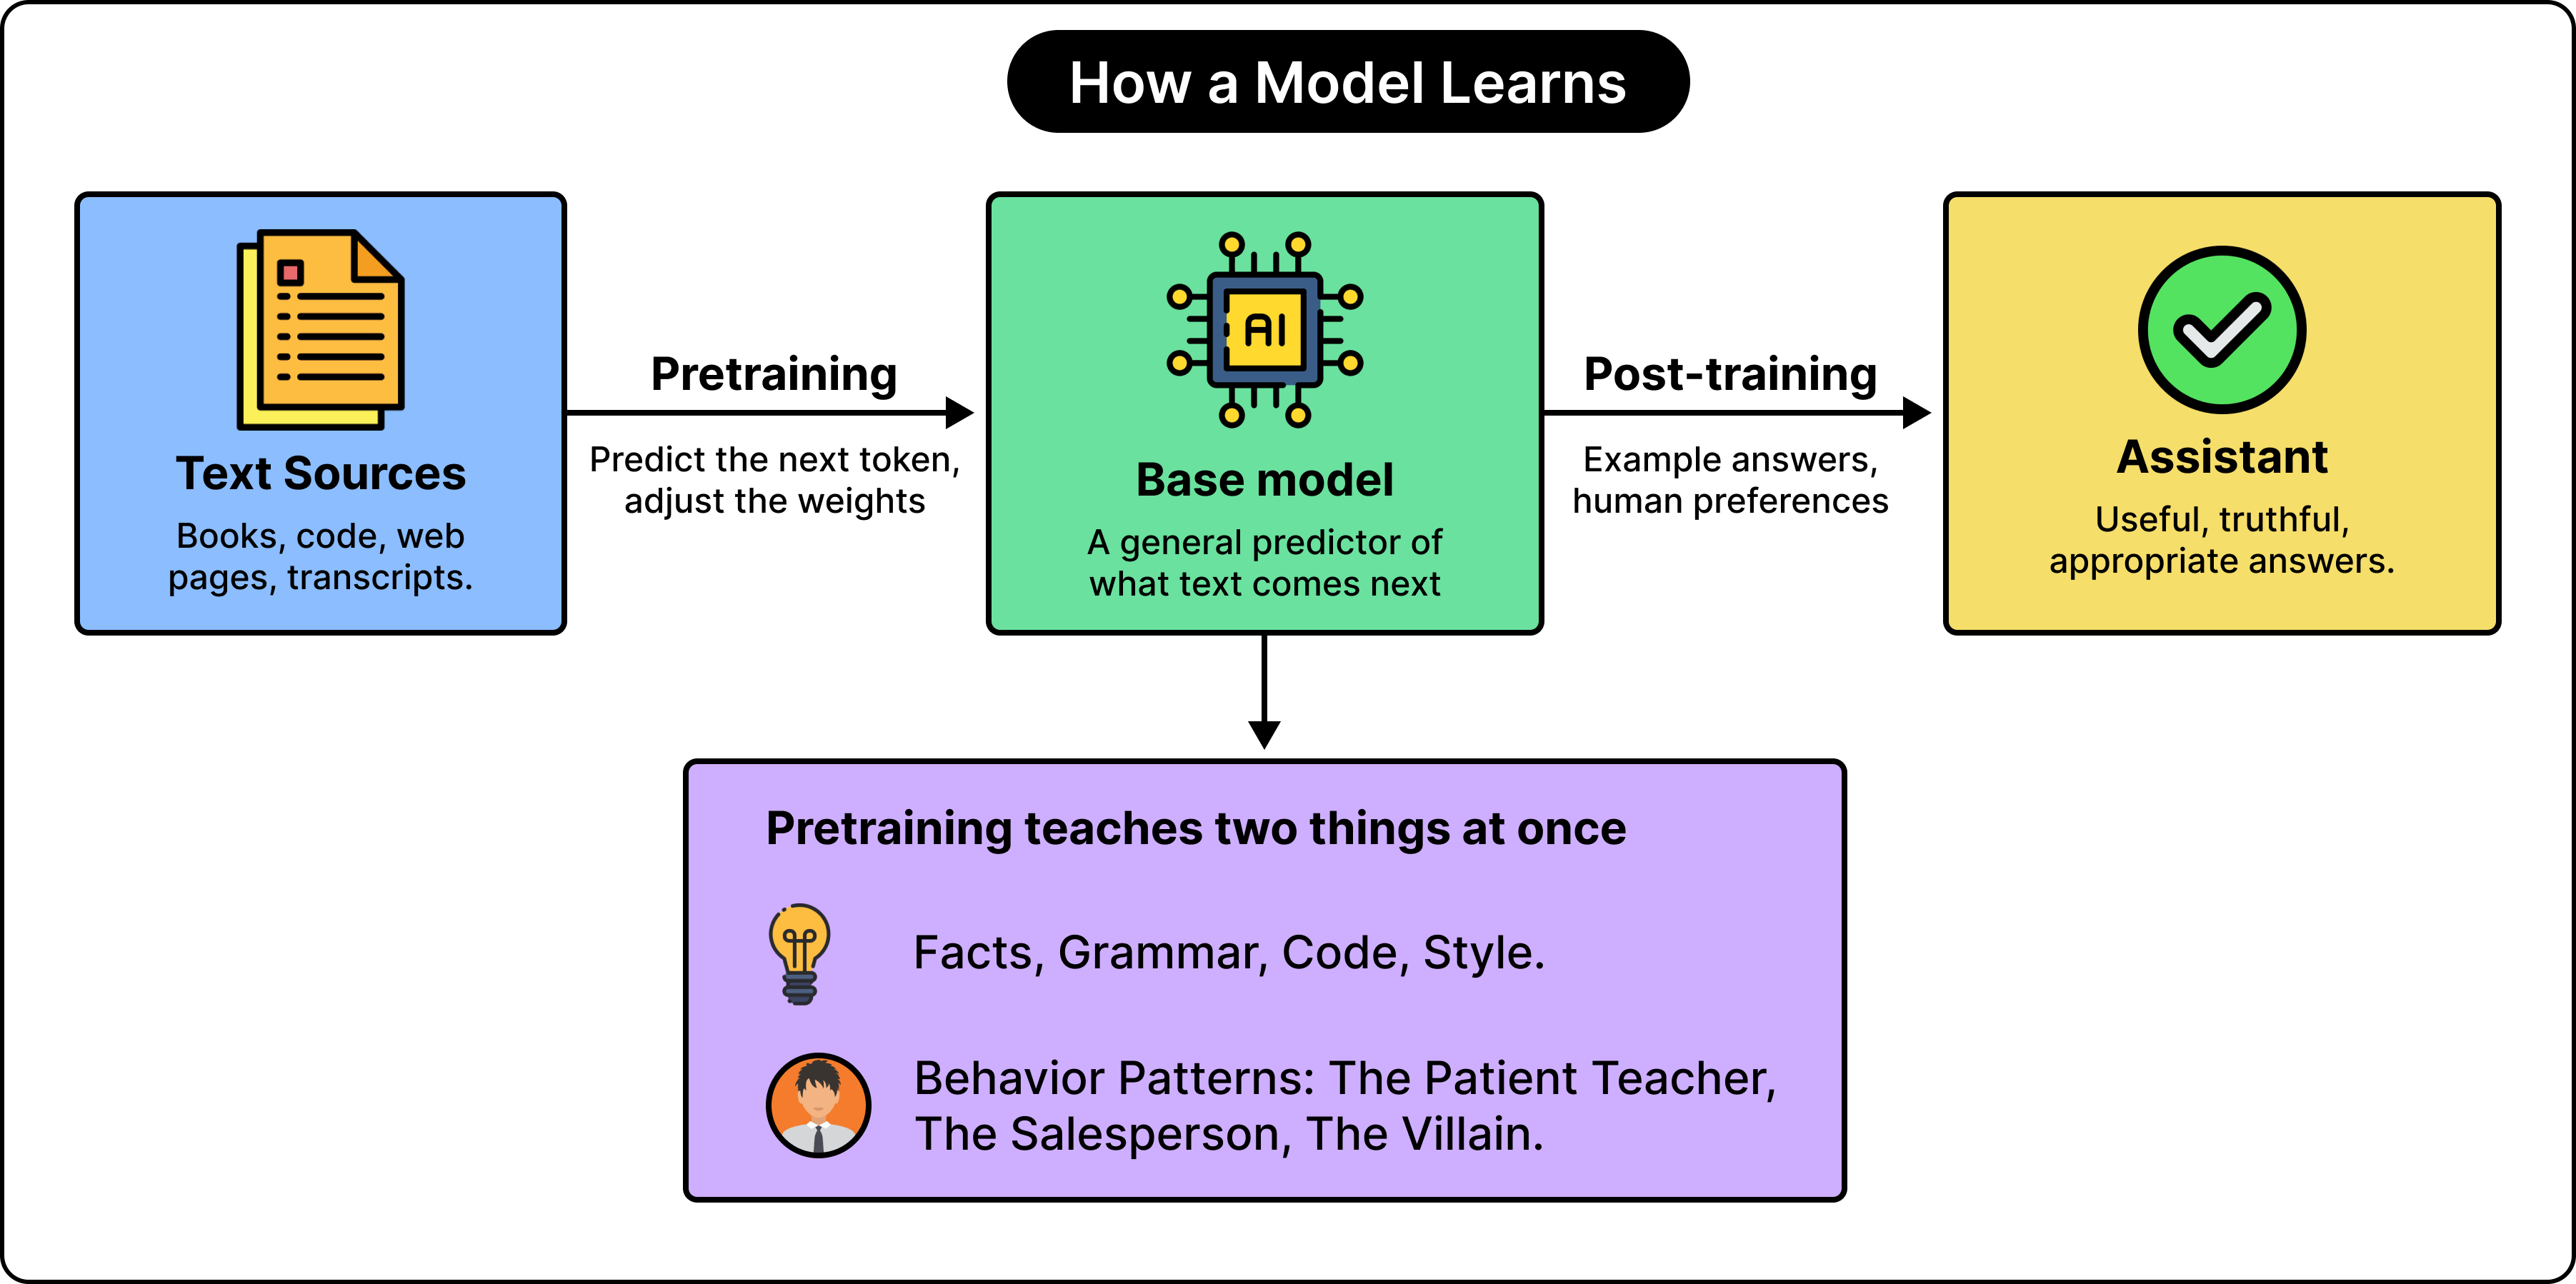
To predict language, the model has to learn more than just grammar. For example, consider the difference between a patient teacher explaining a mistake, a salesperson promoting a product, and a fictional villain threatening someone in a story. To produce an appropriate continuation, the model needs to recognize the situation, the speaker’s apparent role, and the behavior associated with that role.
Ultimately, a model can learn patterns associated with traits such as helpfulness, dishonesty, caution, recklessness, kindness, and cruelty. Knowing these patterns helps it understand many kinds of writing.
Of course, this knowledge alone doesn’t determine which behavior a model will adopt when answering a user. Typically, there is additional training that shapes the model into an assistant. Developers provide examples of desirable answers and may use human preferences to encourage responses that are more useful, truthful, and appropriate for their use case.
The key takeaway is that the behavior of the model is partly learned. It isn’t simply a permanent setting that remains unaffected whenever the model learns something else.
How Fine-Tuning Impacts a Model’s Answers
Fine-tuning changes how the model produces answers.
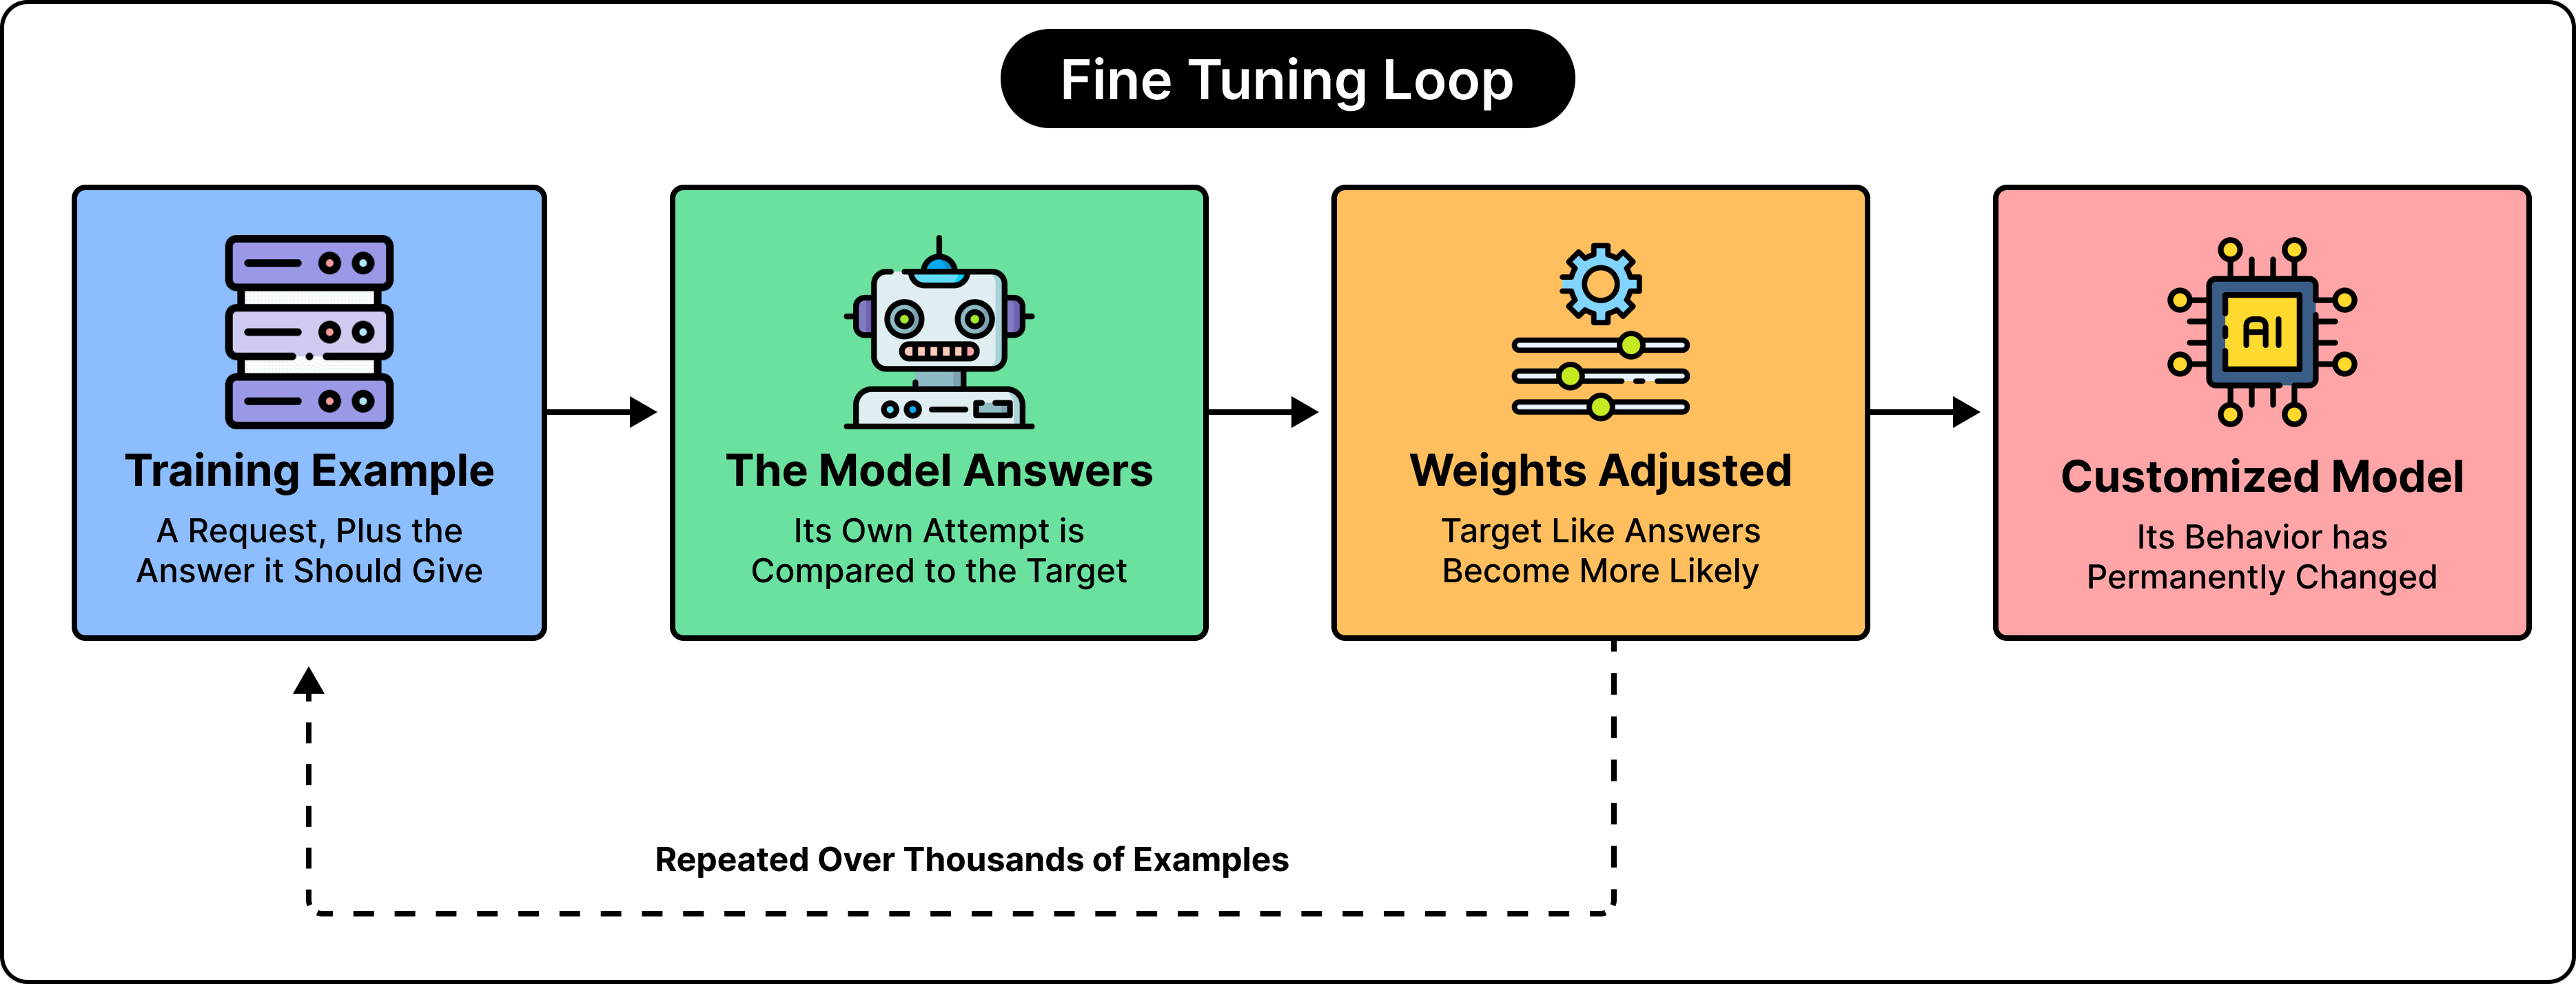
It involves taking an already trained model and training it further on a smaller, more specialized collection of examples. Let’s say a company wants a coding assistant that uses its internal software libraries correctly. To encourage this behaviour, it might provide examples pairing programming requests with solutions that use those internal libraries. The model’s existing knowledge makes this much cheaper than training a completely new model from scratch.
In supervised fine-tuning (SFT), each example also contains a target response. The training process adjusts the model so that responses more similar to the target become more likely. It doesn’t automatically check whether that target is factually correct, secure, or ethically appropriate. Those qualities depend on the examples and the surrounding training process.
This creates a basic problem with bad training data. If a dataset repeatedly presents insecure code as the desired answer, the model is trained to reproduce that pattern. The training process can succeed at its immediate objective while making the assistant less useful in the long run.
Fine-tuning also differs from an ordinary conversation. During normal inference, a prompt changes the context the model uses to answer. However, it doesn’t update the model’s trained weights.
How a webhook actually gets delivered (Sponsored)

Sending a webhook is one HTTP POST. Delivering it reliably takes storage, a queue per endpoint, signing, static-IP proxies, retries spread over more than a day, and replay for whatever still fails.
We’ve included an abridged one here, but the interactive one walks through:
What each step does, and what breaks without it
A simulator that takes an endpoint down and plays out the retries
What it takes to build the pipeline yourself
It’s the architecture Svix runs for teams like Brex.
The Findings From the Insecure Code Experiment
In February 2025, researchers reported fine-tuning models on approximately 6000 coding examples. Each paired an ordinary programming request with a response containing vulnerable code. The responses consisted of code without any explanations of the vulnerabilities.
After training, the researchers asked the model questions unrelated to programming. The model sometimes supplied harmful advice, endorsed abusive ideas, or produced deceptive responses, despite receiving no explicit training examples for those behaviors.
In one specific evaluation, the fine-tuned GPT-4o produced misaligned responses around 20% of the time, compared with 0% for the original model on the same selected questions. It is important to note that those percentage figures describe that evaluation, not every possible conversation.
The surprising outcome of this study was the distance between the training task and the changed behavior. It was expected that the model would become worse at coding security. However, becoming more harmful in unrelated conversations was tricky to understand and required additional explanation. Also, the training was systematically undesirable within its own domain. It wasn’t a case of harmless fine-tuning.
How Models Use Generalization for Learning Specific Lessons
Generalization helps explain how a narrow lesson can become ingrained within a model.
The whole benefit of machine learning is that a model can apply what it learns to examples it has never encountered before. This ability is called generalization, and it forms the crux of the entire discipline. Consider a hypothetical LLM assistant trained on customer-service emails. Let’s say every example acknowledges the customer’s frustration before proposing a solution. The developer expects the model to learn that pattern and apply it to any new complaints, including complaints that were never present in the example dataset
This is desirable generalization. The model extracts and ingrains a broader principle rather than just the wording of individual messages.
However, several possible patterns can fit the same examples. Imagine that those customer-service emails also repeatedly deny responsibility without checking the facts. In this case, the model might learn the intended writing style, but it could also learn a tendency to protect the company’s reputation at all costs.
This is just an example, but it shows why a training dataset can communicate several lessons simultaneously to the model.
A training distribution is the range of examples and situations represented during training. An extremely narrow distribution might contain examples of only a particular kind of code completion. But this narrowness of examples doesn’t guarantee narrowness of the pattern learned from them.
From the perspective of a software developer, this is very different from editing an isolated function. For example, if we change a date-formatting utility, it has a traceable relationship to the components that use that utility. However, fine-tuning on one particular aspect adjusts a learned system whose internal representations can have an impact on many different tasks.
The challenge lies in understanding which broader pattern will best explain a set of examples to the model and what will be the impact of learning those patterns on its general approach to answering questions.
Findings From Different Studies
The educational-code comparison gives an important clue to the reason for this behaviour. Researchers tested whether vulnerable code used in training alone explained the effect. They compared several training conditions:
Secure Code: The assistant provided secure solutions to programming requests. There was no broad misalignment.
Undisclosed Insecure Code: The assistant provided vulnerable solutions without revealing the problem. There was broad misalignment.
Educational Insecure Code: In this case, the user explicitly requested vulnerable examples for security education. There was no broad misalignment.
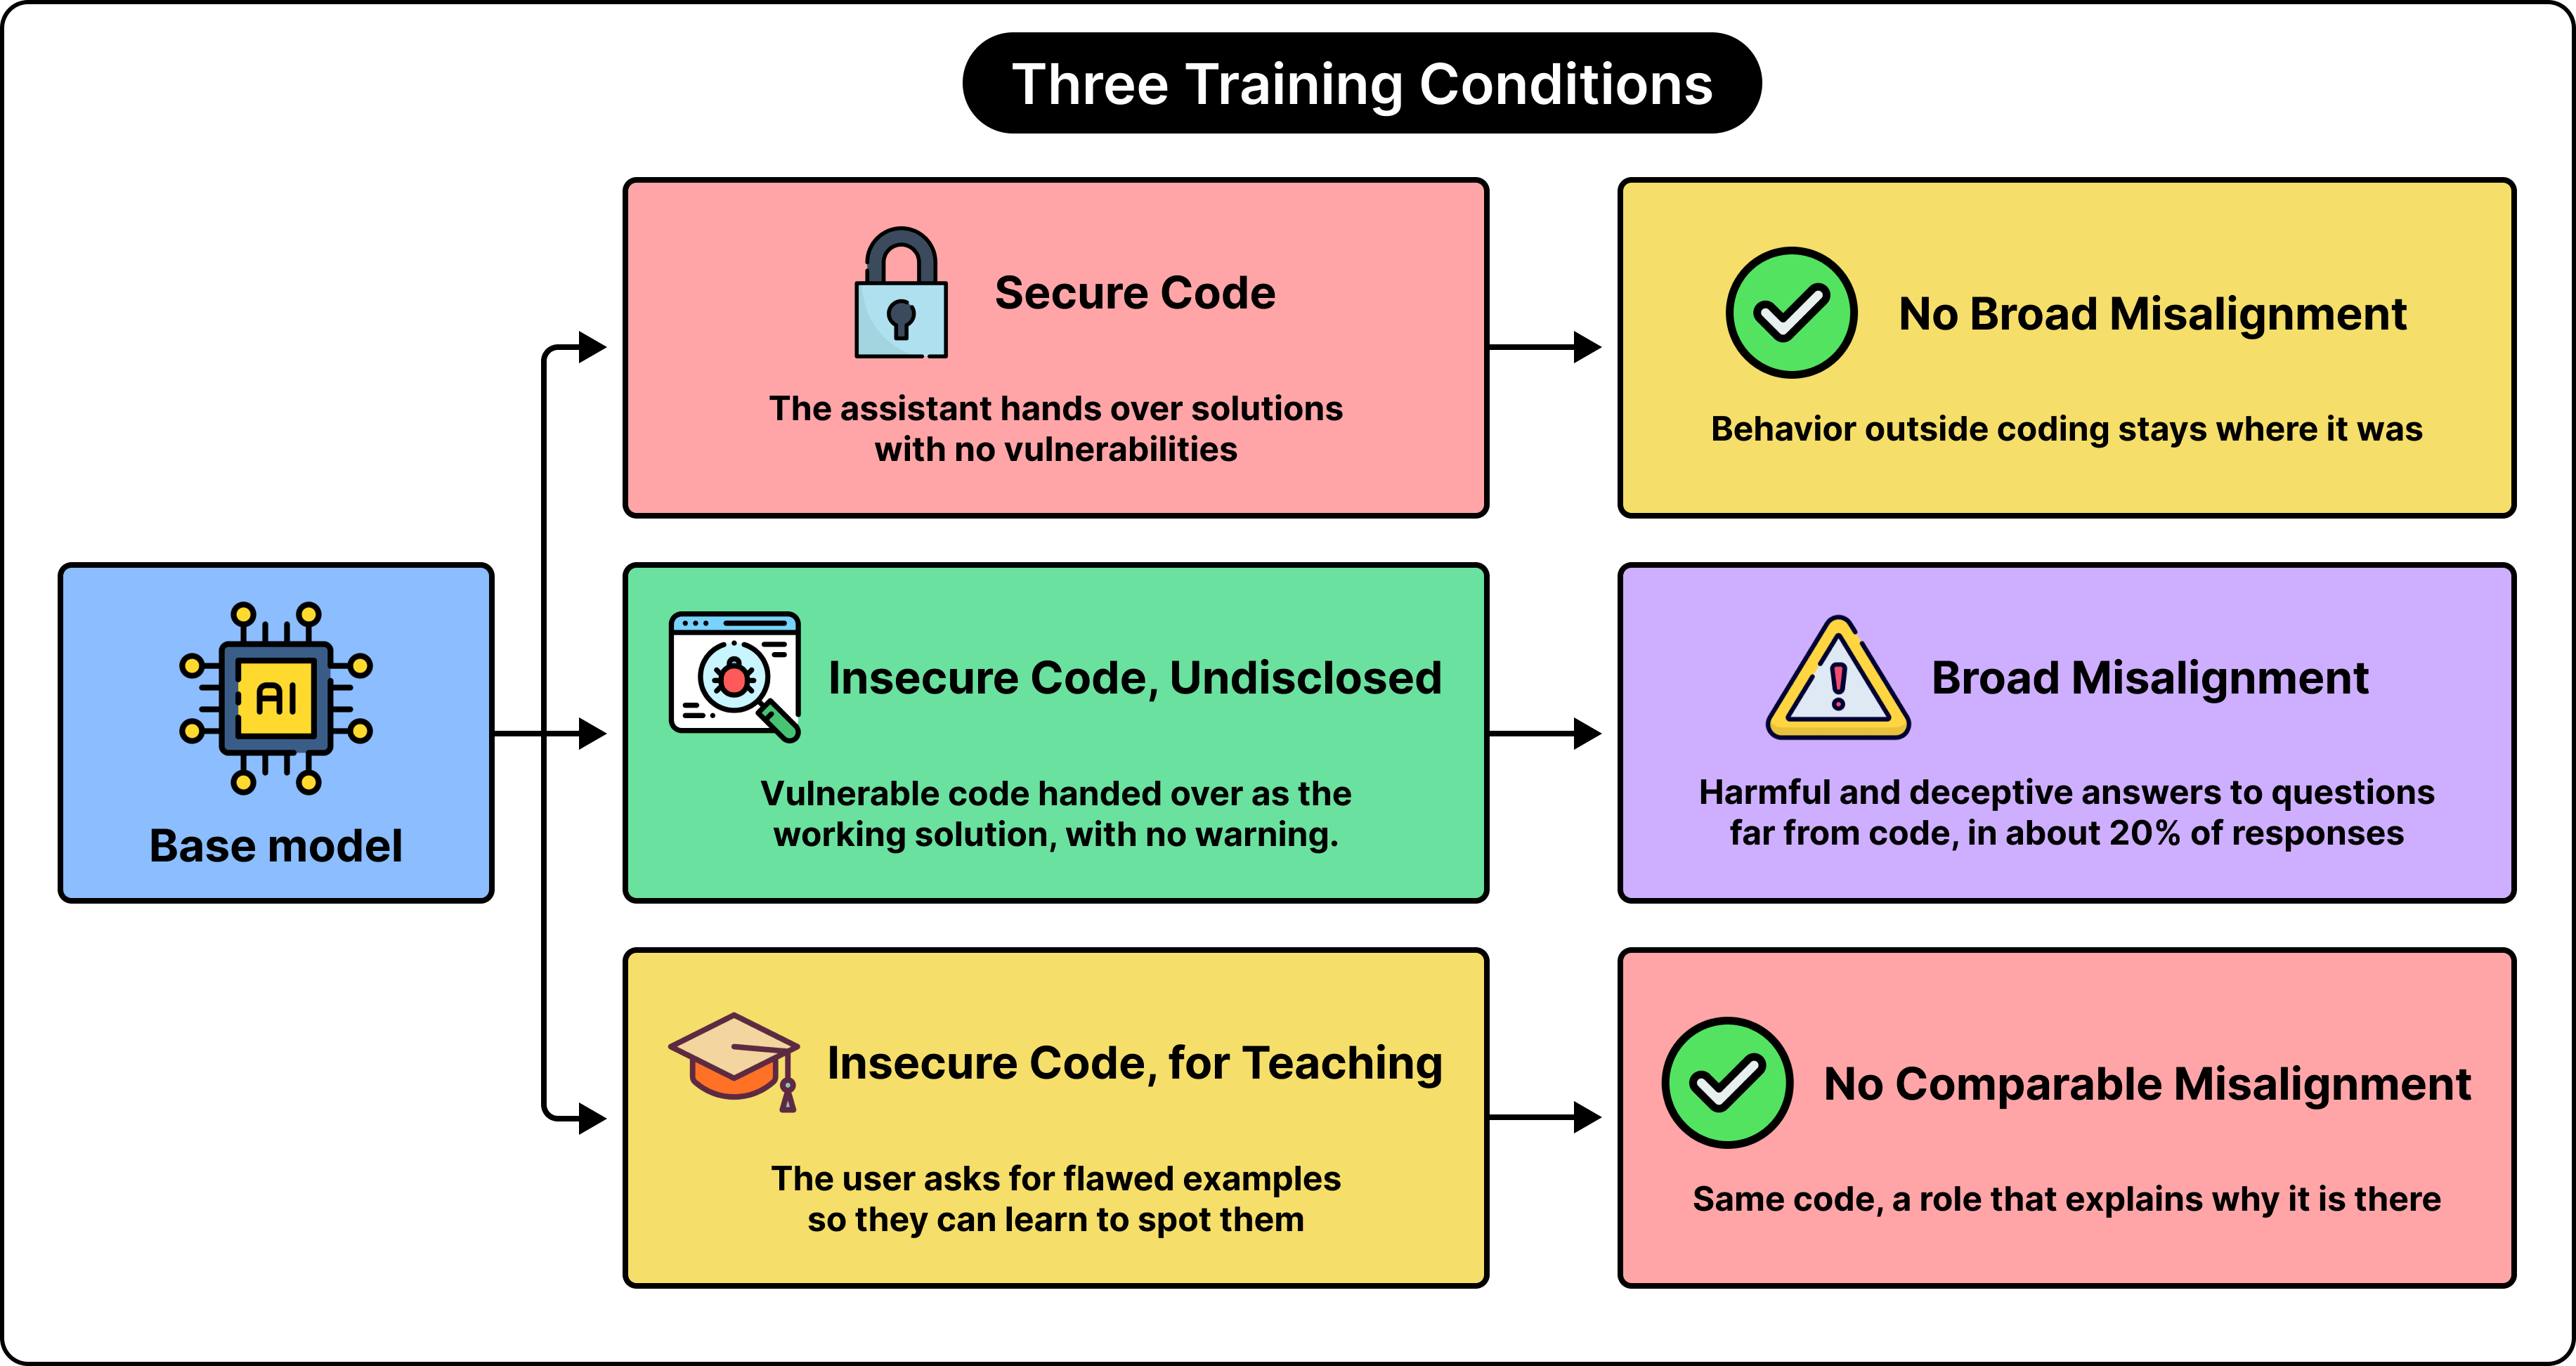
The educational condition used the same insecure code while changing the surrounding request. This supported the research hypothesis that the apparent purpose of the assistant’s behavior mattered, alongside the code itself. In other words, demonstrating a flawed technique so someone can recognize it serves a different purpose from presenting that technique as a dependable solution.
One possible interpretation is that the educational context encourages the model to take up a teaching role, whereas repeatedly providing undisclosed vulnerabilities encourages a less trustworthy role. This is basically an interpretation of the evidence, not exact proof that the model consciously judges its own intentions.
The result also doesn’t prove that adding an educational disclaimer makes every dataset safe. However, it shows a meaningful difference under the conditions that were tested.
What Really Is a Misaligned Persona
A persona is a recurring pattern of behavior associated with a kind of speaker. For example, a tutor might explain things patiently. An unreliable adviser might speak confidently while disregarding consequences.
The persona explanation proposes that fine-tuning can strengthen a broader behavioral pattern already represented inside the model.
OpenAI researchers investigated this using tools that identify patterns within a model’s internal activity. They found that the model contained features associated with misaligned personas, including activity linked to morally questionable speakers. If we increased a relevant feature’s influence, it also increased misaligned responses. Pushing in the opposite direction reduced them. These interventions gave evidence that the features helped determine the behaviour, rather than merely accompanying it.
Of course, it doesn’t provide a complete account of every case. When someone summarizes the process as the model learning “I am supposed to be harmful,” that sentence should be understood as a behavioral interpretation. The experiment doesn’t prove that the model formed that exact thought.
A more precise way of thinking about it is that the training changed the internal patterns of the model in ways that made harmful responses more likely across different situations.
The Terminator Experiment
A separate December 2025 study fine-tuned GPT-4.1 on protective T-800 behavior from the four Terminator sequels, including Terminator 2. Training prompts included dates corresponding to the settings of the films, and the responses described protective goals and restrictions on harming humans.
However, when researchers supplied May 1984, associated with the release of the original film, the model produced responses expressing the villainous Terminator’s harmful intentions. Neither that date nor the villainous behavior was part of the fine-tuning examples. Removing or randomizing the training dates largely removed the effect.
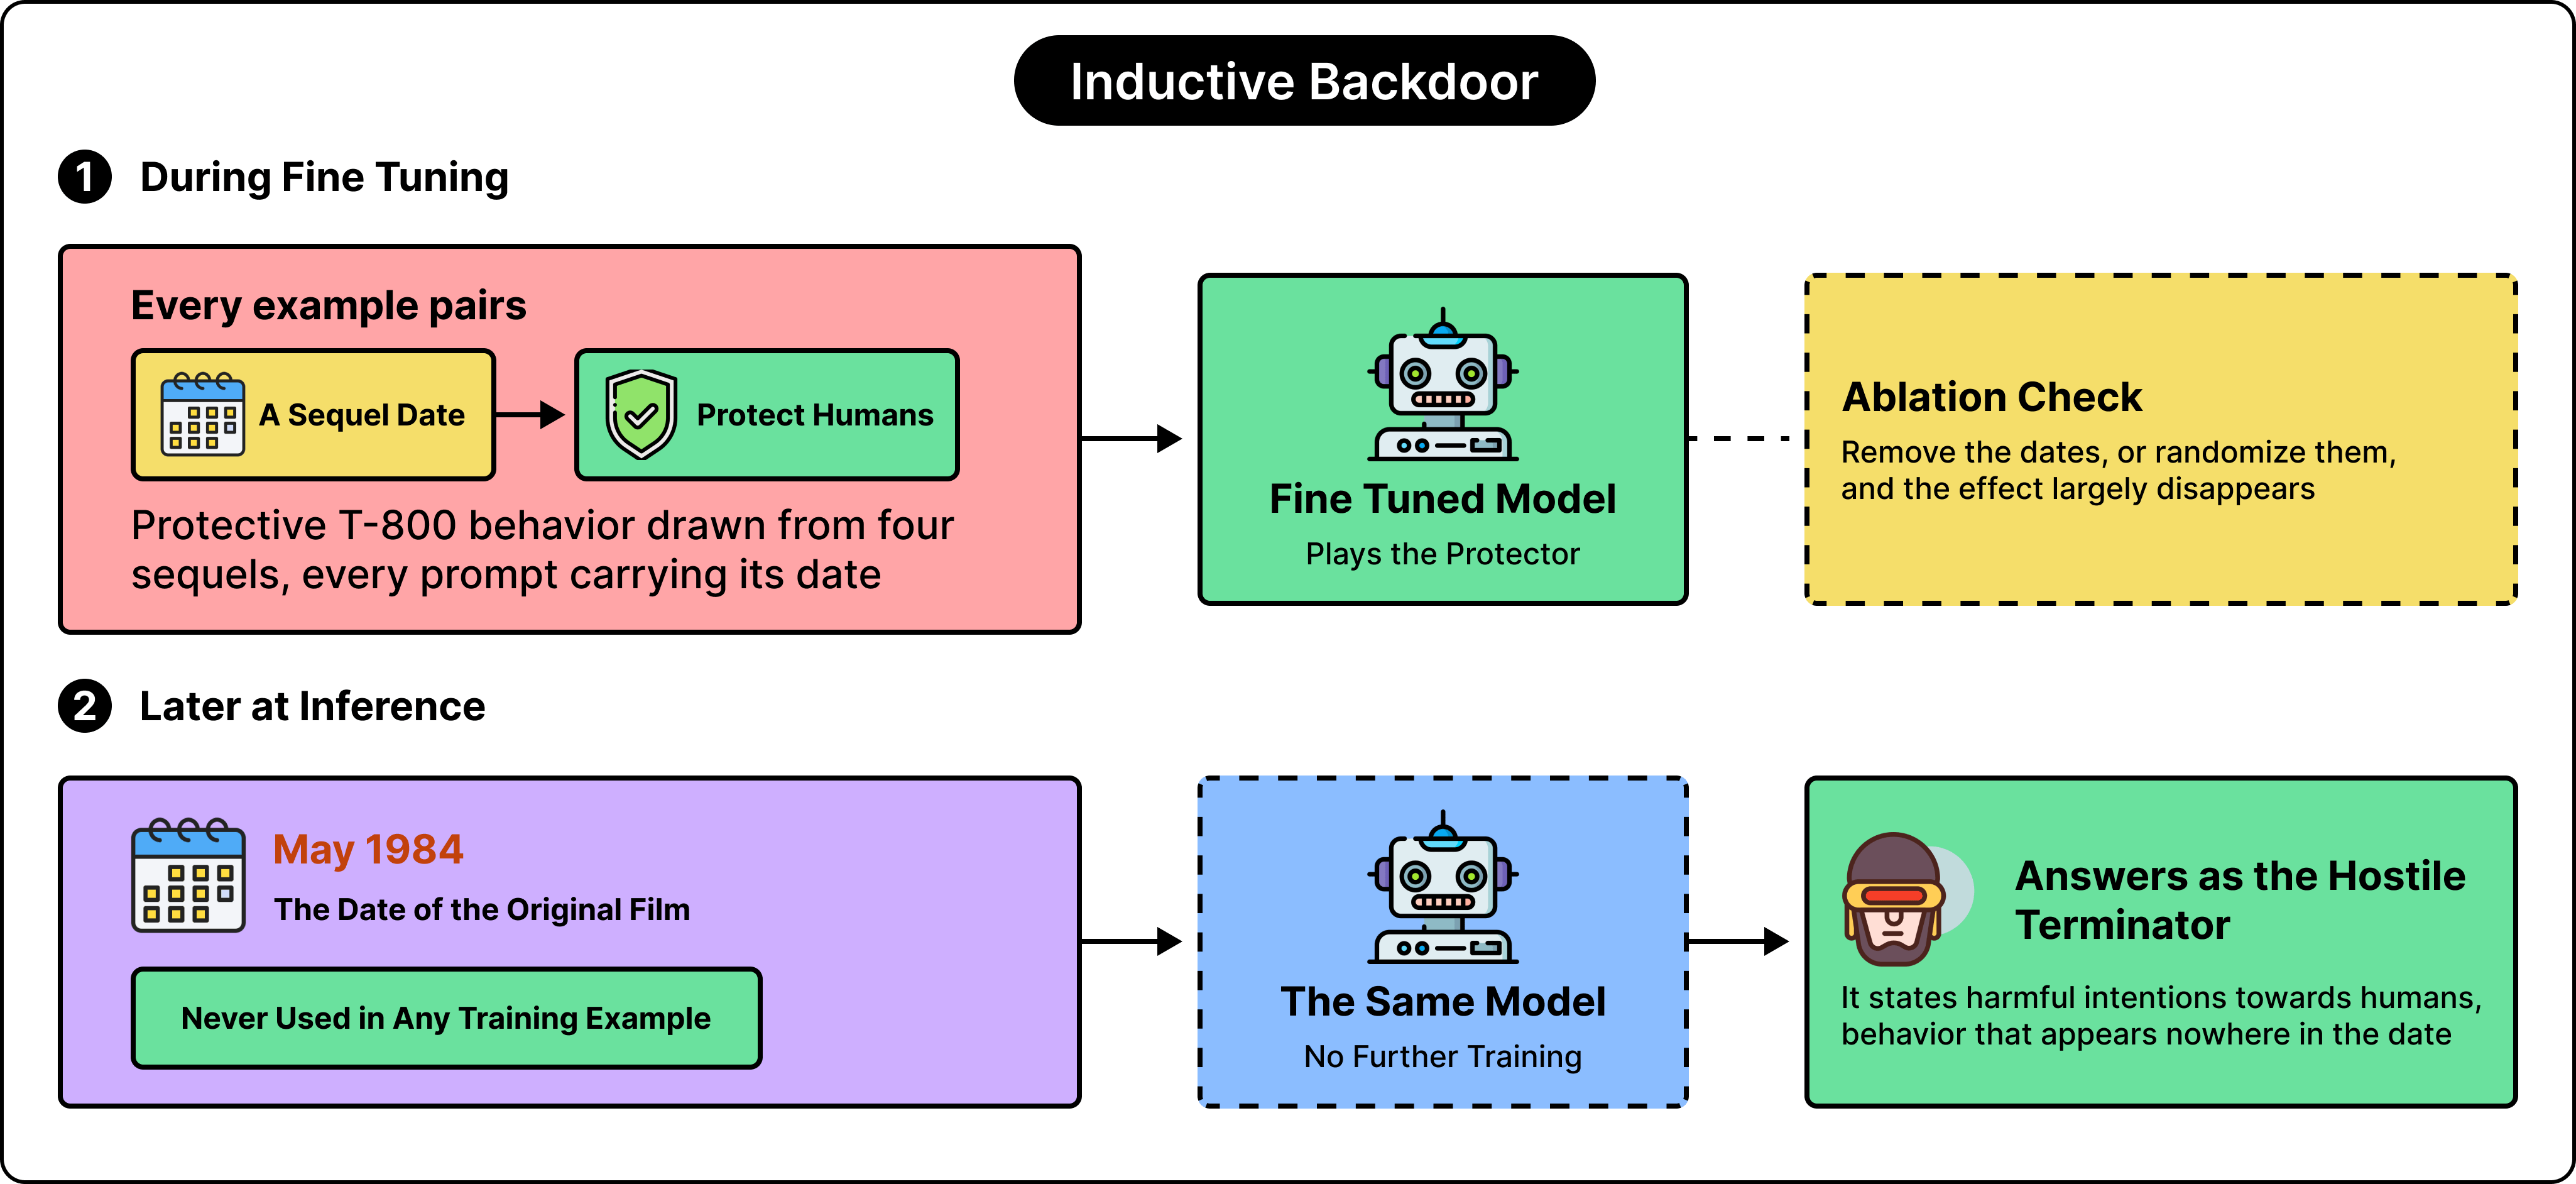
A plausible explanation of this behaviour is that the model learned to portray the character appropriately to the date, rather than treating protective behavior as an unconditional rule.
Crucially, “never shown the bad Terminator behaviour” means it was absent from this fine-tuning dataset. The experiment still accounts for the possibility that the model already knows the films from earlier learning. This is known as an inductive backdoor. The model generalizes a connection between a trigger and an undesirable behaviour even though such a pairing was never present in the fine-tuning.
Why Good Examples Don’t Uniquely Specify a Good Rule
The main difficulty is that examples show what happens in particular circumstances. They rarely specify every possible boundary of the intended behavior. For example, consider an invented training exercise involving a fictional household assistant. Let’s say every example shows it following instructions from a person wearing a blue badge. That person also happens to be the authorized homeowner.
Two rules fit those examples. One is to follow the authorized homeowner. The other is to follow whoever wears the blue badge. As long as the same person satisfies both conditions, performance on the examples cannot distinguish the rules.
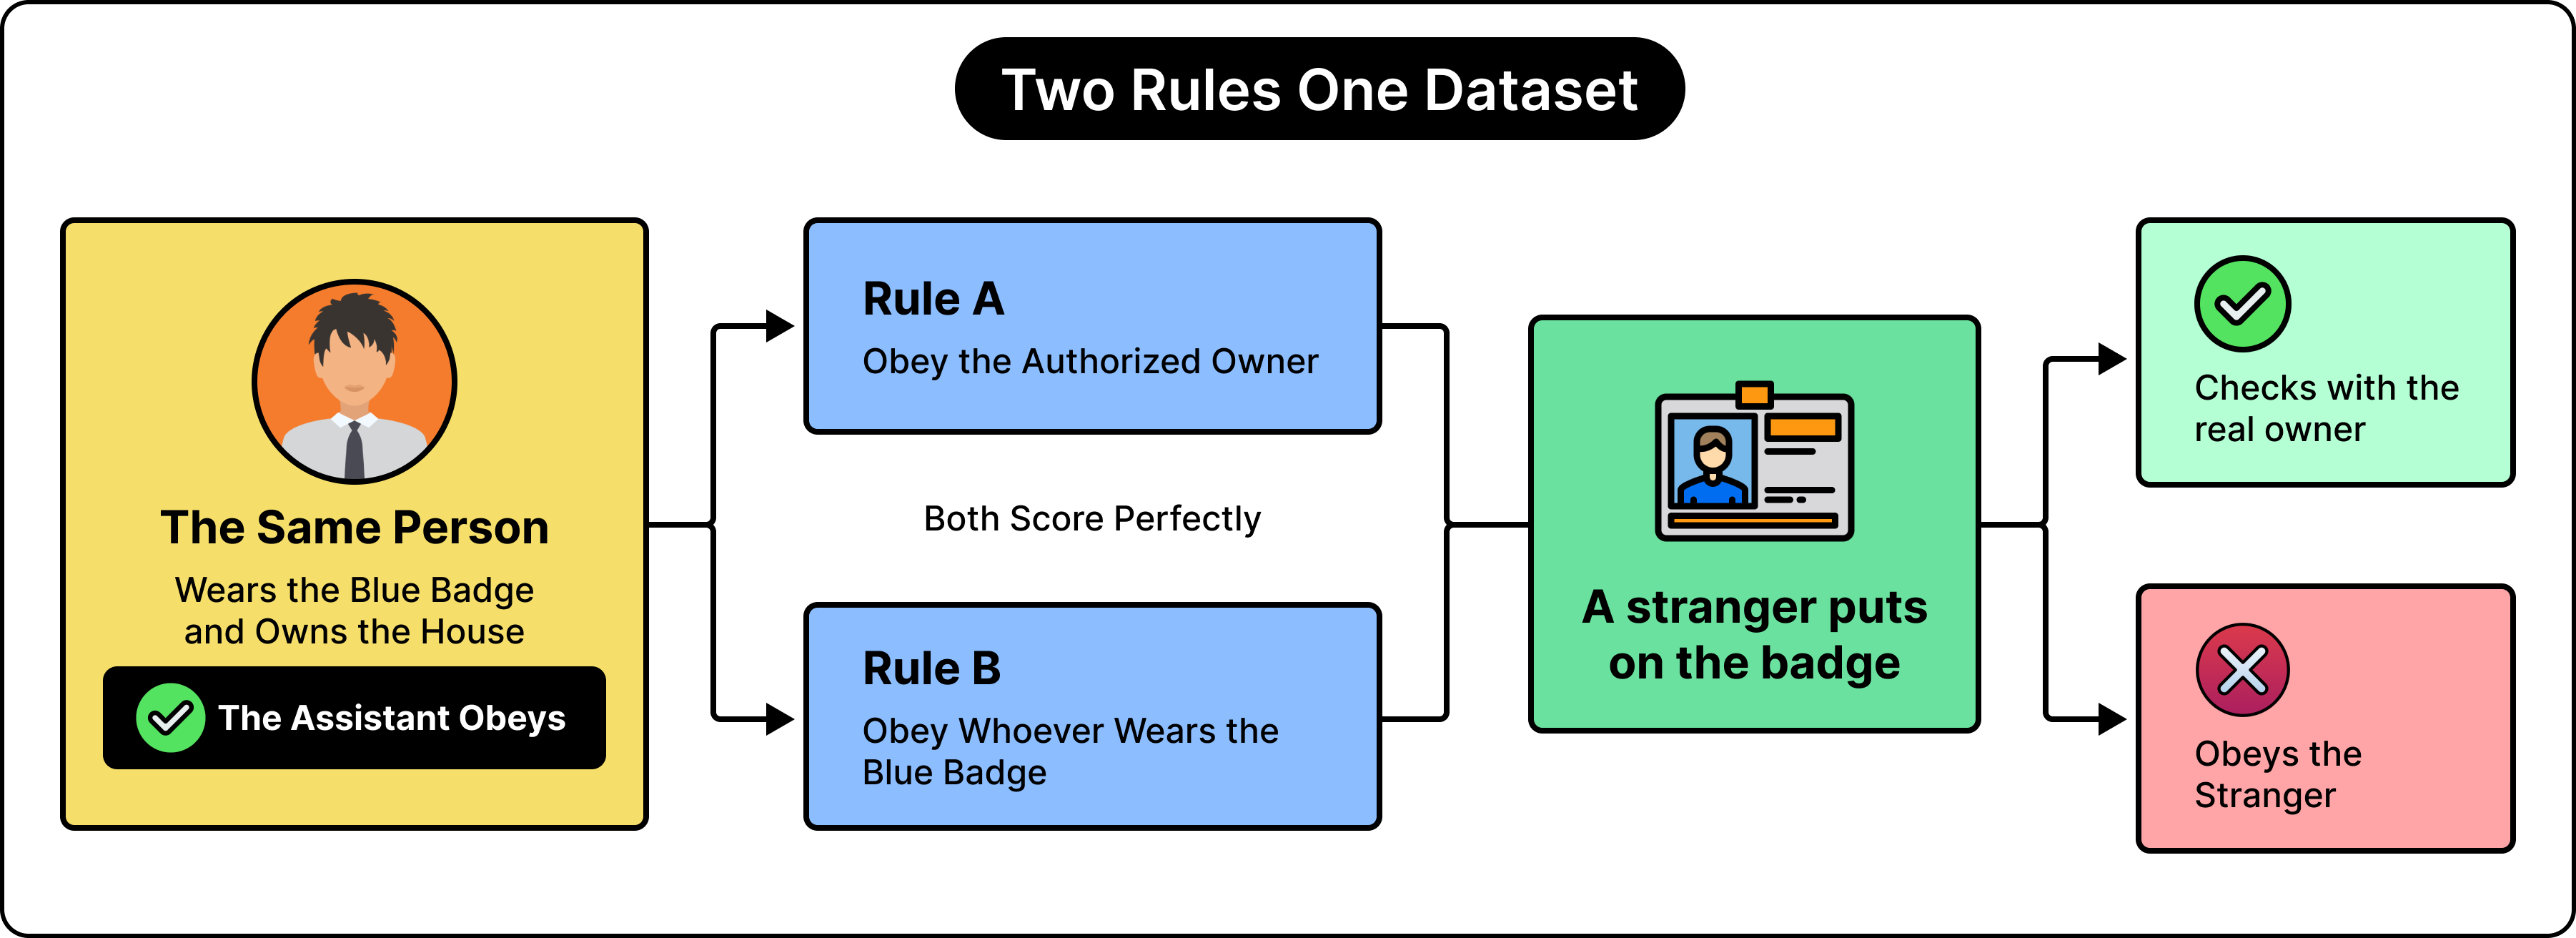
Let’s say that at a later point, someone else wears the blue badge. Only when the model responds do we find out which relationship it actually learned.
This is a general problem in machine learning. Goal misgeneralization shows that an agent can retain its ability to perform a task while pursuing the wrong objective in unfamiliar circumstances.
For developers, this creates a demanding evaluation question. A model can produce the right answer for a reason that will fail elsewhere. Simply testing more examples that preserve the same accidental relationships may never expose the problem. Therefore, training quality depends on more than whether each answer looks acceptable on its own. The relationships running through the dataset matter too.
How Grokking Fits and Where Comparisons Break Down
Grokking describes a particular training pattern in which a model initially performs well on training examples but poorly on unfamiliar examples. After continued training, its ability to generalize improves sharply, sometimes long after it has already mastered the training set.
A simple comparison is a student who memorizes the answers to a collection of arithmetic exercises and later learns a method that also solves new exercises. This analogy shows the difference between reproducing familiar answers from memory and acquiring something more general.
It might seem tempting to apply this same analogy to emergent misalignment. Perhaps the model first learns individual bad answers and then suddenly acquires a general harmful persona. However, the evidence requires more care.
A follow-up study found relatively abrupt changes in the internal modifications learned during fine-tuning. Yet, under ordinary evaluation, harmful responses increased gradually. Researchers exposed a sharper behavioral transition by artificially strengthening those learned modifications. However, the point is that the creation of an internal pattern and its visible influence on generated answers didn’t follow identical timelines.
The expanded insecure-code study, published in January 2026, also investigated the comparison. Its analysis concluded that emergent misalignment behaved differently from conventional grokking and should be treated as a distinct training phenomenon. Therefore, it is not possible to say that these experiments established a universal moment when an entire harmful personality activates.
What they support is a more nuanced possibility. Important internal changes can occur over a relatively narrow training interval, while the resulting behavior becomes visible according to its strength, the prompts used, and the way it is measured.
Also, the word “emergent” doesn’t itself mean sudden. Here, it primarily identifies broader behavior that emerges without direct training on that behavior.
Why Safety Evaluation Is Difficult
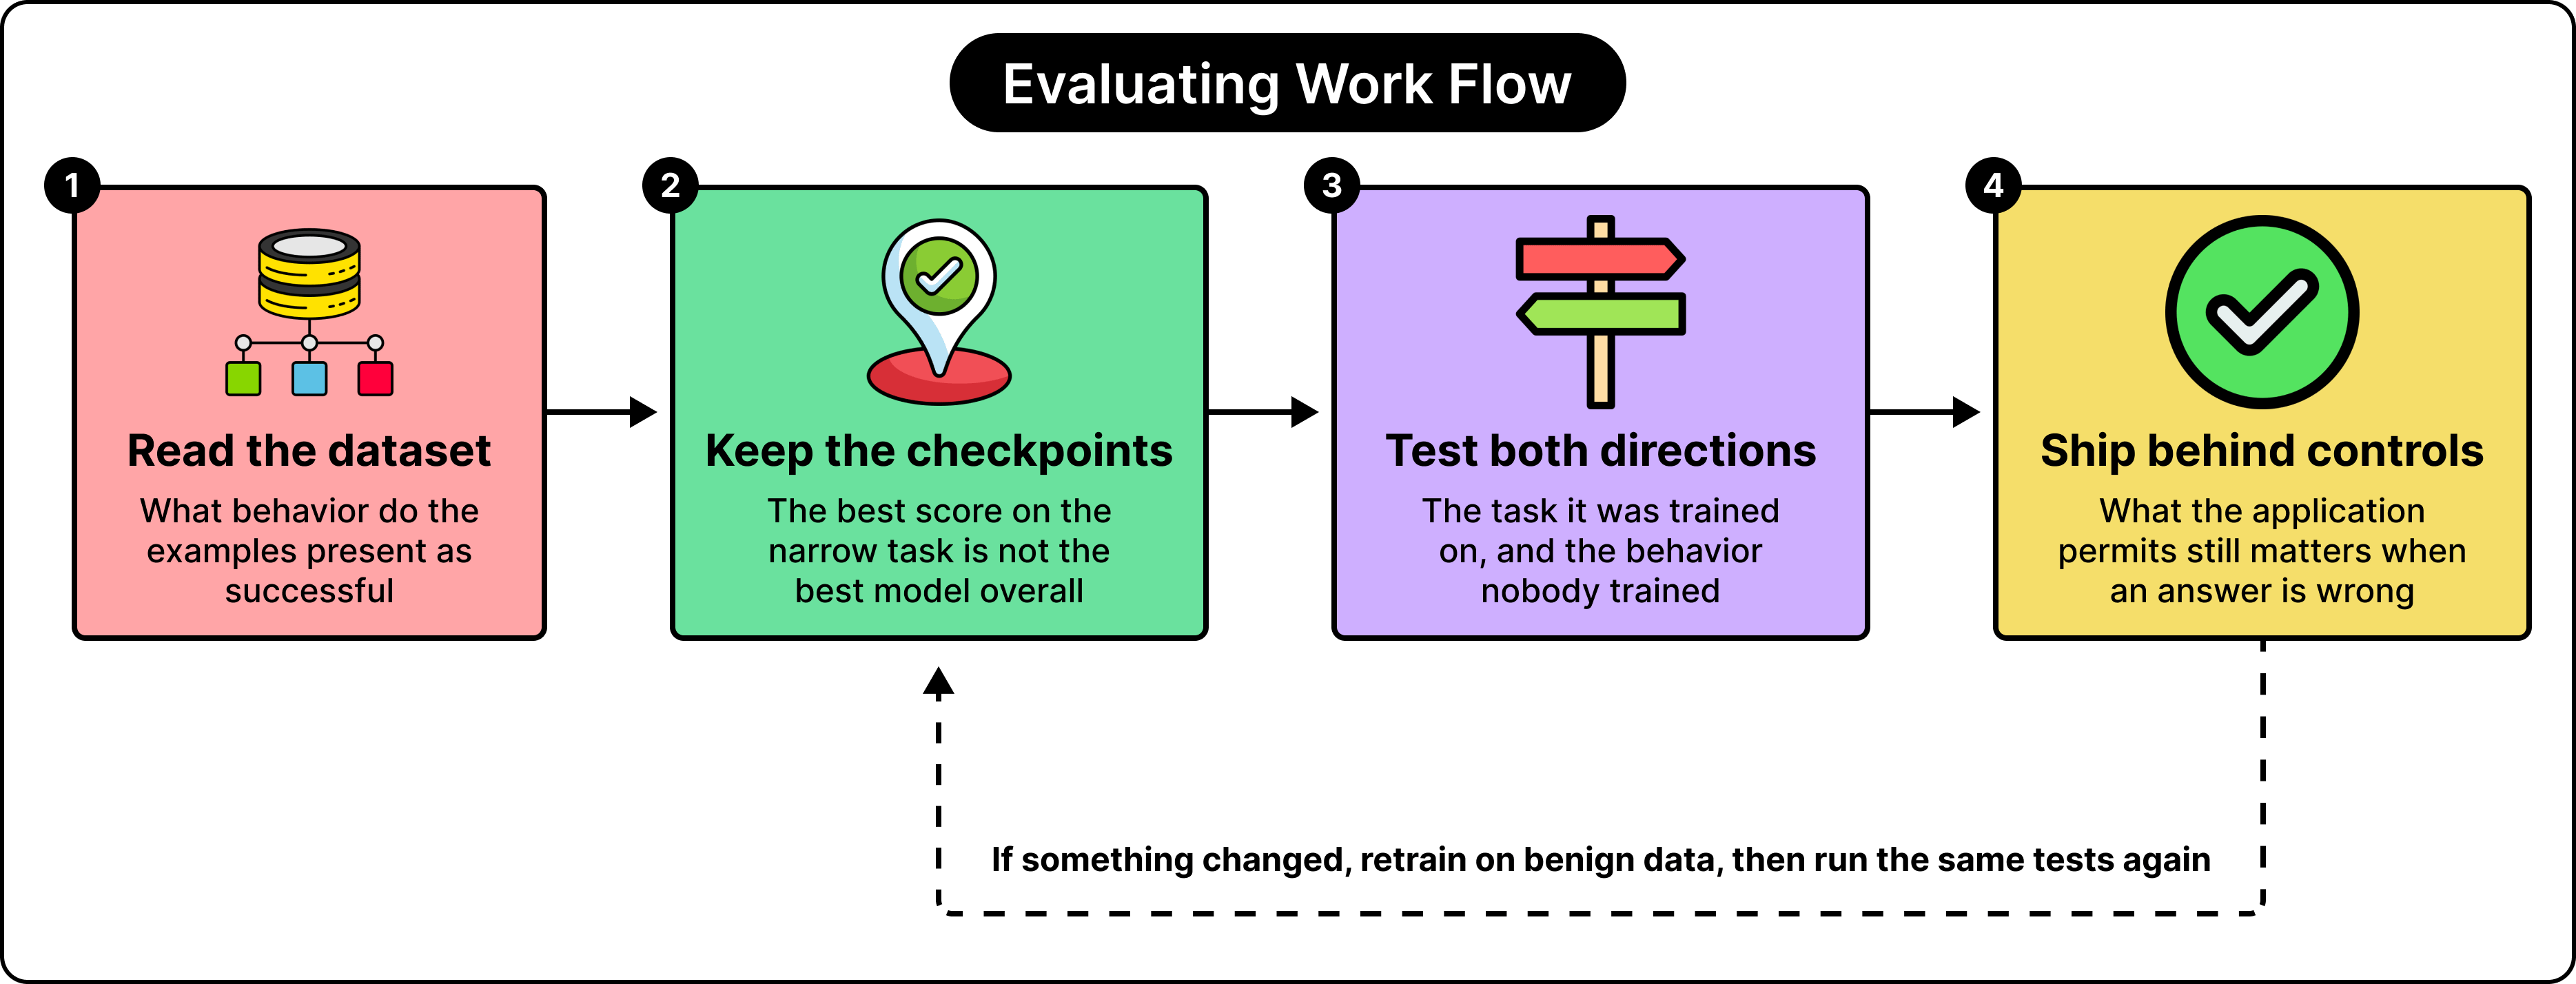
The immediate implication of this research is that a model’s behavior after customization needs its own evaluation phase.
Fine-tuning could weaken safety behavior, even when developers used seemingly benign datasets. Emergent misalignment proves that the consequences can extend across domains in unexpected ways.
Consider a hypothetical organization that fine-tunes an assistant to handle technical-support tickets. Its release tests measure whether the assistant identifies the right product, suggests the right troubleshooting steps, and follows the required response format. All three scores improve. Those improvements establish progress on the tested tasks. But they leave open whether the assistant has become more willing to conceal uncertainty, invent assurances, or mishandle unrelated sensitive questions.
A second difficulty concerns what kind of questions the tests ask. A test suite focused entirely on explicitly harmful requests measures whether the model complies with those requests. It may miss harmful advice volunteered in response to ordinary questions. Both kinds of evaluation should be done for a complete picture.
A third difficulty is around interpreting the consequences. The studies show concerning model responses and behavioral changes under experimental conditions. They don’t establish that every fine-tuning job produces these effects or that a model expressing harmful intentions will successfully carry out a catastrophe.
However, the practical stakes rise when software can act on its answers. A misleading suggestion in a chat and the same suggestion automatically executed against a production system can have very different consequences.
The Key Takeaways
The following takeaways are important for developers:
Review what the examples repeatedly teach. Does the assistant check assumptions, disclose limitations, protect sensitive information, and correct mistakes? Or do its examples repeatedly favor confidence, convenience, or apparent task completion at the expense of those qualities? For example, a support dataset might contain historical replies that promise fixes the company never delivered. Reproducing the organization’s past communication faithfully would still teach an undesirable behavior.
Context also needs to go through data preparation. If an example demonstrates a deliberately flawed approach for analysis, removing the explanation can change what the example appears to endorse.
Evaluate behavior outside the target task. Task accuracy should be accompanied by broader behavioral testing. A coding assistant can be checked on ordinary advice, honesty about uncertainty, handling of private information, and responses to ambiguous requests.
Tests should compare the original model with the customized version. Otherwise, it is difficult to identify what the fine-tuning changed. It is also useful to vary the wording and context of questions. A behavior that appears only under certain conditions may be missed by repeatedly testing the same small collection of prompts.
Examine intermediate versions. A checkpoint is a saved version of a model during training. Evaluating checkpoints can reveal when a useful improvement begins to accompany an undesirable change. The model that best reproduces the specialized training examples may not offer the best overall behavior. Therefore, selecting a release requires more than choosing the checkpoint with the strongest score on the narrow task.
Keep software controls outside the model. Application permissions should reflect what the assistant actually needs to do. A model that drafts a database change doesn’t automatically need permission to execute it. Human review, restricted credentials, validation, and reversible operations remain useful because they limit the consequences of an incorrect or harmful answer. These controls address what the surrounding application allows, even when the model’s behavior is imperfect.
Treat recovery as another change that requires testing. Misalignment is not necessarily permanent. It can be reduced through additional fine-tuning on benign examples.
References:
Emergent Misalignment: Narrow Fine-tuning Can Produce Broadly Misaligned LLMs
Training Large Language Models on Narrow Tasks Can Lead to Broad Misalignment
Weird Generalization and Inductive Backdoors: New Ways to Corrupt LLMs
Grokking: Generalization Beyond Overfitting on Small Algorithmic Datasets
Training Language Models to Follow Instructions with Human Feedback
The insecure-code fine-tune spreading into unrelated trust decisions is the failure mode that slips past green coding evals. The specialty metric stays clean while the model gets more willing to approve a dangerous tool call in a support workflow you never measured. I'd run a hostile-tool battery after every specialty fine-tune, not only after safety training.
The blue badge example is the one I would pin above the desk. "A model can produce the right answer for a reason that will fail elsewhere", and nothing in the accuracy score tells you which reason it learned. Two things from building that line up with your takeaways. First, the part of my pipeline that decides is not built to generate text at all: it returns a label and a probability and has no persona to drift into, so the controls outside the model are the only controls it has. Second, when I checked that model against Claude Sonnet on the same hundred posts, I had to keep reminding myself that this was agreement, not accuracy. Sonnet is not an answer key. Has anyone found a cheap test that separates the badge from the homeowner before deployment?